<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://www.neilghosh.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://www.neilghosh.com/" rel="alternate" type="text/html" /><updated>2026-07-17T17:45:49+00:00</updated><id>https://www.neilghosh.com/feed.xml</id><title type="html">Neil Ghosh</title><subtitle>Knowledge has no value until it is practiced !</subtitle><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><entry><title type="html">20 Years on Reflextions …</title><link href="https://www.neilghosh.com/2026/07/20-years-on-reflextions.html" rel="alternate" type="text/html" title="20 Years on Reflextions …" /><published>2026-07-17T00:00:00+00:00</published><updated>2026-07-17T00:00:00+00:00</updated><id>https://www.neilghosh.com/2026/07/20-years-on-reflextions</id><content type="html" xml:base="https://www.neilghosh.com/2026/07/20-years-on-reflextions.html"><![CDATA[<p>This might read a bit like a resume, as I am not really a natural writer and tend to jump straight to the facts in chronological order. Really, this is just a reflection of my career in tech so far. I am incredibly grateful to my colleagues - from my very first manager to the product manager I disagreed with (and regretted days later). Everyone taught me something, even the intern who had a clarity of thought like nobody else on the team. I am also immensely proud of the organizations I managed to be a part of, and the culture and system maturity built over decades by their veterans. Please feel free to comment and remind me of anything that has stayed with you from our interactions. (If it is something negative, you can DM me to resolve it and make peace! :))</p>

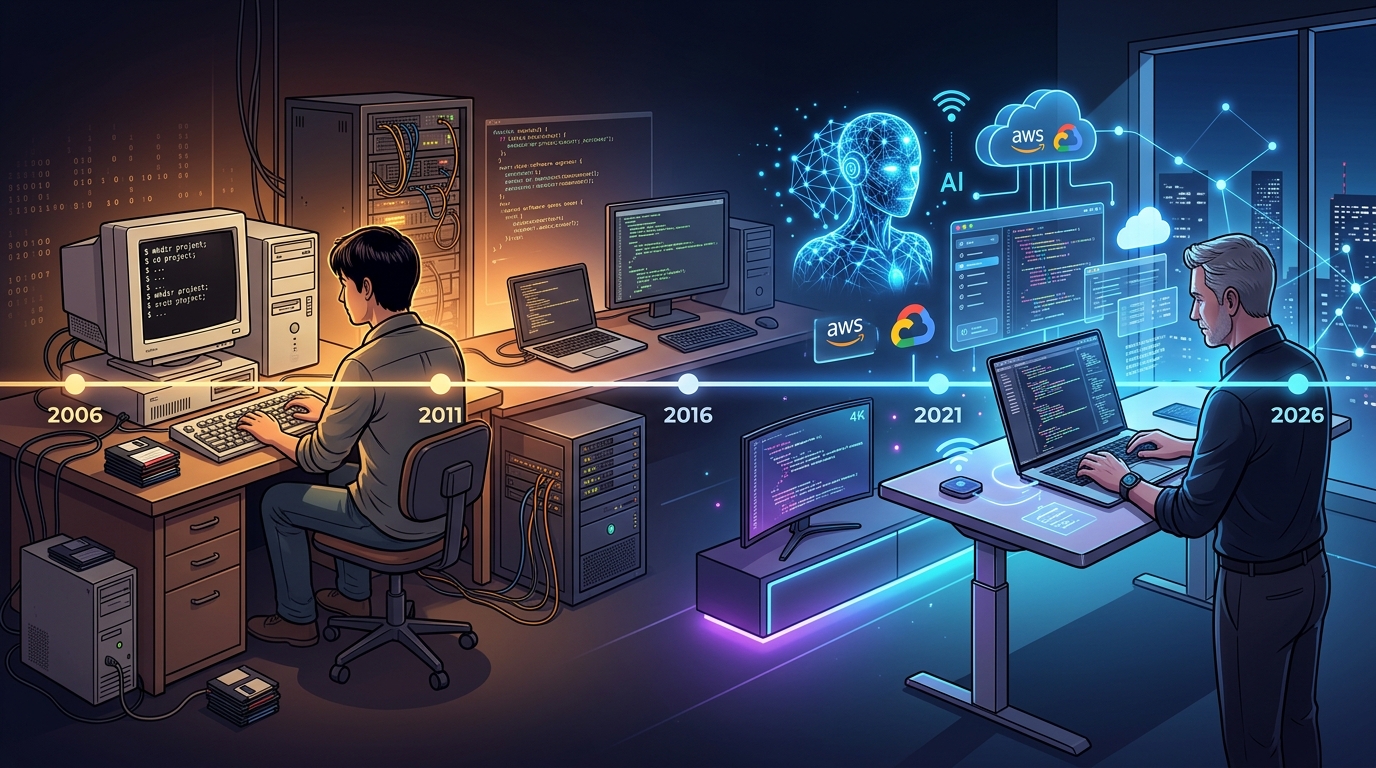
<p><img src="/assets/2026/tech-reflection-journey.jpg" alt="Tech reflection journey timeline 2006 to 2026" /></p>

<p>Twenty years ago today, I embarked on my very first job straight out of college. Coming from a computer science background, I had a solid understanding of programming and building small-scale software, thanks to various mini and major projects. These included reservation systems and designing and administering my college website—for which I used a telnet terminal and an ERNET FTP server to upload content. However, the technology used in real-world production systems was completely different from what I had practiced.</p>

<p>As an eager 21-year-old arriving in Chennai, it was decided (likely at random) that I would be trained on <a href="https://www.oracle.com/applications/">Oracle Apps</a> and assigned to a project. Since it was a service-based company, these were client-facing projects. Although university had taught me SQL and <a href="https://www.oracle.com/database/">Oracle databases</a>, I had no idea how to build software with them without a programming language like <a href="https://www.java.com/">Java</a>. Following training—which I topped by the narrowest of margins—my work revolved primarily around <a href="https://www.oracle.com/database/technologies/developer-tools/forms.html">Oracle Forms</a>, which allowed users to input and save data into an Oracle database, and <a href="https://www.oracle.com/database/technologies/developer-tools/reports.html">Reports</a>, which formatted and displayed that data on the screen. All of this was part of Oracle Apps, an Enterprise Resource Planning (ERP) system, similar to <a href="https://www.sap.com/">SAP</a>.</p>

<p>After nearly a year, I relocated to Hyderabad to join a very small company—what we would call a bootstrapped startup today—focused on financial technology. My role involved downloading stock exchange data using <a href="https://www.bloomberg.com/professional/support/api-library/">Bloomberg’s C API</a> and storing it in a <a href="https://www.postgresql.org/">PostgreSQL</a> database. We built web portals to analyze and present this data, and even performed “what-if” analyses on stock and option data. Much of our prototyping started in <a href="https://www.microsoft.com/en-us/microsoft-365/excel">Microsoft Excel</a> with <a href="https://learn.microsoft.com/en-us/office/vba/api/overview/">VBA</a> scripting before being migrated to a production stack of <a href="https://www.php.net/">PHP</a>, <a href="https://httpd.apache.org/">Apache</a>, and PostgreSQL on <a href="https://www.linux.org/">Linux</a> servers. We used PostgreSQL instead of <a href="https://www.mysql.com/">MySQL</a> because it was closer to Oracle, free, and, unlike MySQL at the time, fully supported views.</p>

<p>One of the most interesting aspects of that role was developing stock charts and a custom chat application. Because JavaScript libraries weren’t mature enough yet to build native stock charts like Open-High-Low-Close (OHLC) charts, we adopted <a href="https://en.wikipedia.org/wiki/Apache_Flex">Adobe Flex</a>. Flex was a rising technology for building Rich Internet Applications (RIAs), powered by <a href="https://en.wikipedia.org/wiki/ActionScript">ActionScript</a> (the language behind <a href="https://en.wikipedia.org/wiki/Adobe_Flash">Adobe Flash</a>) and <a href="https://en.wikipedia.org/wiki/MXML">MXML</a>, a declarative markup language used to define the user interface. Since it was licensed software, we initially explored an open-source alternative called <a href="https://en.wikipedia.org/wiki/OpenLaszlo">OpenLaszlo</a>, but we eventually abandoned it due to lack of maturity and stuck with Adobe. The beauty of Adobe Flex and <a href="https://en.wikipedia.org/wiki/Adobe_AIR">Adobe AIR</a> was their ability to compile into standalone desktop executables for Windows and other platforms. Our primary limitation was file I/O, as it was originally built for browsers and could only write to a specific directory called “fscommand”. We also experimented with <a href="https://en.wikipedia.org/wiki/Visual_Basic">Visual Basic</a>, which offered better performance and did not require the Flash runtime.</p>

<p>For the chat application, PHP turned out to be our best option. While PHP had a reputation for being fragile, we utilized it in a strongly-typed, object-oriented manner. This was back in 2007, and we drew heavy inspiration from <a href="https://www.skype.com/">Skype</a>, which we relied on for international voice calls and group chats. We tailored our chat system specifically for the financial domain. Looking back, this startup environment is where I experienced the fastest professional growth of my entire career.</p>

<p>My next move was to a technology giant, which gave me my first look at the culture of a major product organization. The scale was massive, featuring an array of in-house tooling including proprietary email, conferencing, and build systems. It was an exceptional place to work and profoundly shaped my career. I spent over five years there across multiple teams, largely continuing the Oracle application work from my first job—but this time, building it as a vendor. It was a remarkable period; we were delivering rich, browser-based applications where updating data without refreshing the page (partial page rendering) was still a major feat. Although <a href="https://developer.mozilla.org/en-US/docs/Web/Guide/AJAX">Ajax</a> had been adopted by Gmail three years prior, it had not yet taken hold in the enterprise space. Oracle used a lightweight JRE called <a href="https://en.wikipedia.org/wiki/JInitiator">JInitiator</a>, which downloaded to the desktop on first access and launched <a href="https://en.wikipedia.org/wiki/Java_applet">Java applets</a> directly from the browser. While Forms and Reports handled transactional workflows, background tasks were powered by concurrent programs running <a href="https://www.oracle.com/database/technologies/appdev/plsql.html">PL/SQL</a> or shell scripts.</p>

<p>The domain at this point was Supply Chain, where terms like Purchase Order, Sales Order, and Consigned Inventory were predominant. The mobile version of the application ran on handheld devices with a DOS prompt connecting to a telnet server powered by Java. It is worth remembering that the iPhone had not even been born yet.</p>

<p>This was where I met people who went on to build truly remarkable things. In my view, Oracle served as a vital stepping stone and career accelerator for many entry-level engineers. We managed to navigate the 2008 financial crisis together, forging incredible connections that remain strong to this day.</p>

<p>At that time, social media in India was predominantly <a href="https://en.wikipedia.org/wiki/Orkut">Orkut</a>, though by 2008, <a href="https://www.facebook.com/">Facebook</a> and <a href="https://twitter.com/">Twitter</a> began grabbing major market share. <a href="https://en.wikipedia.org/wiki/Yahoo!_Messenger">Yahoo Messenger</a> was also soon replaced by <a href="https://en.wikipedia.org/wiki/Google_Talk">Google Talk</a>, which was lightweight and embedded right inside Gmail.</p>

<p>Sometime around 2010, I became fascinated by web services and began building them inside Oracle. While Oracle already had <a href="https://en.wikipedia.org/wiki/Service-oriented_architecture">SOA</a>, which prominently relied on <a href="https://en.wikipedia.org/wiki/SOAP">SOAP</a> (and all the WSDL complexity), the simplicity of <a href="https://en.wikipedia.org/wiki/Representational_state_transfer">REST</a> captured my interest. Around the same time, <a href="https://en.wikipedia.org/wiki/Sun_Microsystems">Sun Microsystems</a> was acquired by Oracle, making Java a central focus of innovation with new technologies like <a href="https://openjfx.io/">JavaFX</a>, <a href="https://eclipse-ee4j.github.io/glassfish/">GlassFish</a>, and <a href="https://netbeans.apache.org/">NetBeans</a>.</p>

<p>With the introduction of <a href="https://cloud.google.com/appengine">Google App Engine</a>, I developed a strong interest in <a href="https://en.wikipedia.org/wiki/Platform_as_a_service">Platform as a Service (PaaS)</a> and started using it for my personal projects. Back in 2009, it only supported Python, but once Java support was added, I decided to take a gamble and change my domain altogether.</p>

<p>This transition welcomed me into the world of gaming, which was culturally very different. For the first time, I was collaborating with an incredibly diverse group of people, including designers, artists, and product managers. Even the engineers working on the game clients were highly specialized, possessing deep knowledge of game engines and physics. Working at <a href="https://www.ea.com/">Electronic Arts (EA)</a> was an incredibly fast-paced experience, both in terms of technology and people. Within months, your project could change, features could be shut down, or you might find yourself working with team members from a completely different region of the globe. One of the greatest lessons I learned there was how to be truly agile—sometimes you only found out the day’s top priority that morning. I also traveled extensively to other studios during this time, which gave me firsthand insight into the work culture and discipline of other parts of the world, especially the USA and Canada.</p>

<p>One of my notable projects at EA was working on the <a href="https://www.playwsop.com/">World Series of Poker</a>, which introduced me to the functional programming paradigm of <a href="https://www.erlang.org/">Erlang</a> and <a href="https://elixir-lang.org/">Elixir</a>. It completely changed how I thought about procedures and variables. Another project was <a href="https://www.ea.com/games/monopoly-bingo">Monopoly Bingo</a>, which squeezed out every bit of potential from the then-limited Google App Engine. Because <a href="https://cloud.google.com/datastore">Datastore</a> was our only persistence layer (which was NoSQL), our architecture had to be designed around key-based access rather than traditional SQL filters. Since writing to storage was expensive but compute was cheap and horizontally scalable, we leveraged techniques like sequential random number generators instead of storing every state. We jokingly called this “cost-oriented programming” 🙂.</p>

<p>It was a project of many firsts in my career: we used <a href="https://gatling.io/">Gatling</a> for load testing, <a href="https://www.swrve.com/">Swrve</a> for A/B testing, <a href="https://www.pagerduty.com/">PagerDuty</a> for alerting, and <a href="https://testng.org/">TestNG</a> for unit tests. We even utilized <a href="https://www.incredibuild.com/">Incredibuild</a> to harness the idle power of everyone’s desktop machines to accelerate our build system. Later, I worked on titles like <a href="https://en.wikipedia.org/wiki/Tetris_Blitz">Tetris Blitz</a> and <a href="https://www.ea.com/games/bejeweled/bejeweled-blitz">Bejeweled Blitz</a>, which used a LAMP stack. This was my first time using <a href="https://aws.amazon.com/">AWS</a> as the main cloud provider, giving me a chance to brush up on PHP, which I hadn’t touched in years. Similar to Google’s Datastore, we used <a href="https://www.couchbase.com/">Couchbase</a> for NoSQL, which eventually transitioned to <a href="https://aws.amazon.com/dynamodb/">DynamoDB</a> in the Amazon ecosystem, while <a href="https://aws.amazon.com/elasticache/">ElastiCache</a> served as our equivalent to App Engine’s Memcache. Since <a href="https://kubernetes.io/">Kubernetes</a> didn’t exist yet, everything ran on individual VMs behind a load balancer.</p>

<p>Later, I moved to <a href="https://en.wikipedia.org/wiki/Blue_Yonder">JDA</a>, which was completely a Google shop. By then, <a href="https://cloud.google.com/">Google Cloud Platform</a> offered a rich suite of services, including <a href="https://cloud.google.com/bigquery">BigQuery</a>, <a href="https://cloud.google.com/dataflow">Dataflow</a>, <a href="https://cloud.google.com/storage">Cloud Storage</a>, <a href="https://cloud.google.com/sql">Cloud SQL</a>, and <a href="https://cloud.google.com/pubsub">Pub/Sub</a>. We used BigQuery and Dataflow to handle high-scale data ingestion and validation, while Pub/Sub enabled us to scale out, ultimately saving master data in Cloud SQL to service the <a href="https://angular.dev/">Angular</a>-facing APIs. Principles like Single Source of Truth (SSOT), Infrastructure as Code (IaC), Keep It Simple, Stupid (KISS), and “You Aren’t Gonna Need It” (YAGNI) became our daily buzzwords. Ultimately, this role provided a huge learning curve on how to operate in a modern cloud environment, designing multiple microservices that interacted not just through synchronous REST calls, but also via Pub/Sub push and pull subscriptions.</p>

<p>My next major milestone was at <a href="https://www.salesforce.com/">Salesforce</a>, where we built the Loyalty System from the ground up on their highly mature and adaptable platform. It was incredible to experience how much out-of-the-box functionality was available with minimal custom code—a testament to a platform versatile enough to support virtually any business domain. Indeed, with <a href="https://developer.salesforce.com/docs/atlas.en-us.apexcode.meta/apexcode/apex_intro_what_is_apex.htm">Apex</a> on the backend and <a href="https://developer.salesforce.com/docs/platform/lwc/overview">LWC</a> on the frontend, one can construct robust applications in hours without worrying about database management, web servers, or API routing. This role served as a masterclass in maximizing the utility of reusable shared components across various teams and organizational units, while also bringing valuable exposure to <a href="https://www.gitops.tech/">GitOps</a>, service-to-service communication configurations, and IAM roles.</p>

<p>Currently, I am at <a href="https://www.microsoft.com/">Microsoft</a>, a role that offers our team the autonomy to select our technology stack and own our projects end-to-end—from infrastructure at the VM and container level to requirement design, always treating security and compliance as non-negotiable foundations. It has been a rewarding journey so far, diving deep into everything from the fundamentals of authentication and public key infrastructure (PKI) to the consumer security domain. Working alongside AI as a co-developer has fundamentally transformed the development experience compared to years past. It is an incredibly exciting time to build, with boundless opportunities ahead for what we can create and deliver.</p>

<p>Two decades later, technology exists in an entirely different dimension. While I sometimes miss the days of sharing high-resolution photos on <a href="https://www.flickr.com/">Flickr</a>, it is incredibly exciting to connect with so many people who share my interests on <a href="https://www.instagram.com/">Instagram</a> and <a href="https://www.linkedin.com/">LinkedIn</a>. Although the current wave of AI-generated “slop” is frustrating and makes finding genuine information difficult, I believe a consolidation is inevitable. Platforms will eventually adapt to user feedback, learning to surface what actually matters and letting low-effort content fade away, ultimately discouraging those looking for shortcuts.</p>

<p>I do miss the clean, chronological flow of linear email threads. Tools like <a href="https://slack.com/">Slack</a> and <a href="https://www.microsoft.com/en-us/microsoft-teams/group-chat-software">Teams</a>, with their constant stream of messages and bot notifications, can feel overwhelming. Yet, there is no denying they make us move faster. With a bit of self-discipline and clear team guidelines on what warrants attention, these channels can be highly streamlined. Indeed, we could never have survived the sudden shift to remote work during COVID-19 without the rapid advancement and adoption of video tools like <a href="https://zoom.us/">Zoom</a> and <a href="https://meet.google.com/">Meet</a>, or collaboration hubs like Slack and Teams.</p>

<p>The convenience today is remarkable. I can reach government authorities with a single click and complete official transactions using <a href="https://uidai.gov.in/">Aadhaar</a> authentication, eliminating the need to print endless photocopies. Airport travel is equally seamless: <a href="https://www.digiyatra.foundation/">Digi Yatra</a> allows me to bypass physical tickets and IDs entirely. I just show my face to pass through airport security scanners—no QR code needed until actual boarding (though a QR is still required while boarding).</p>

<p>It is truly an amazing time. I recently refactored a codebase for a pet project that I had struggled with for five years in just a single night using AI agents. I don’t even write down structured ideas anymore—I just “vibe code” it.</p>

<p>Ultimately, witnessing this twenty-year evolution of technology should help us better distinguish genuine innovation from temporary hype. Hopefully, this shared experience guides us to make the right investments rather than falling prey to knee-jerk reactions.</p>

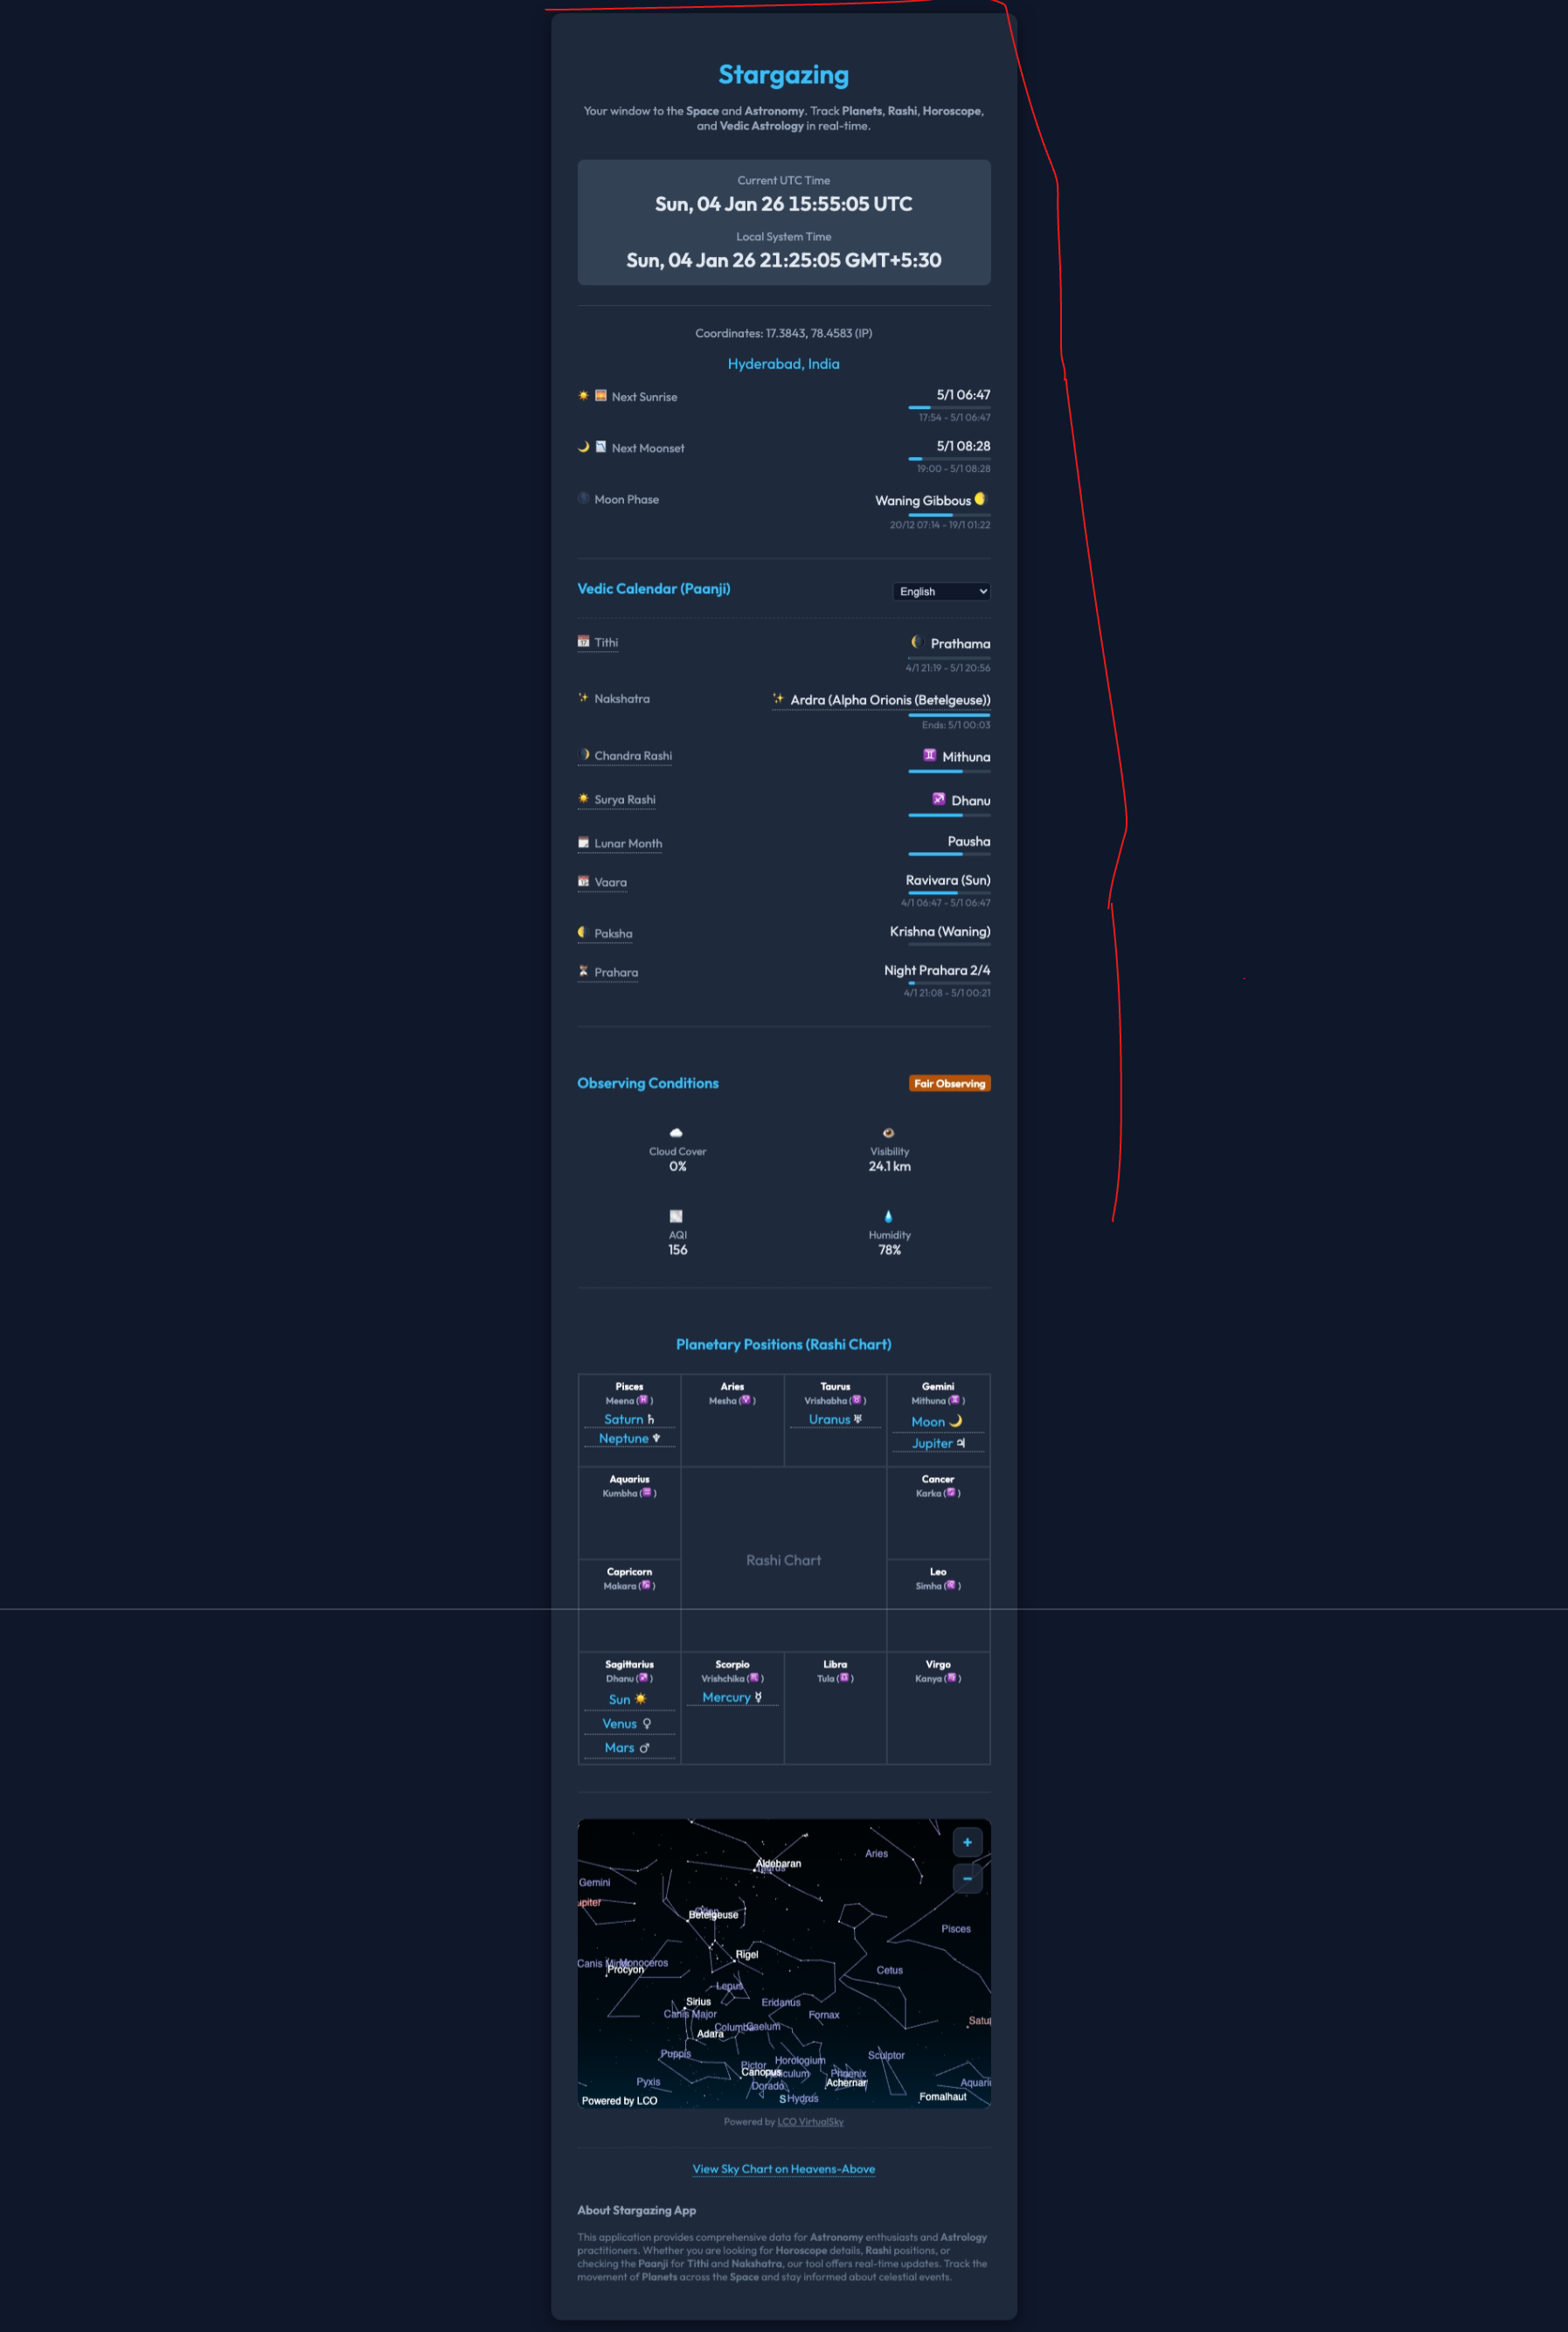
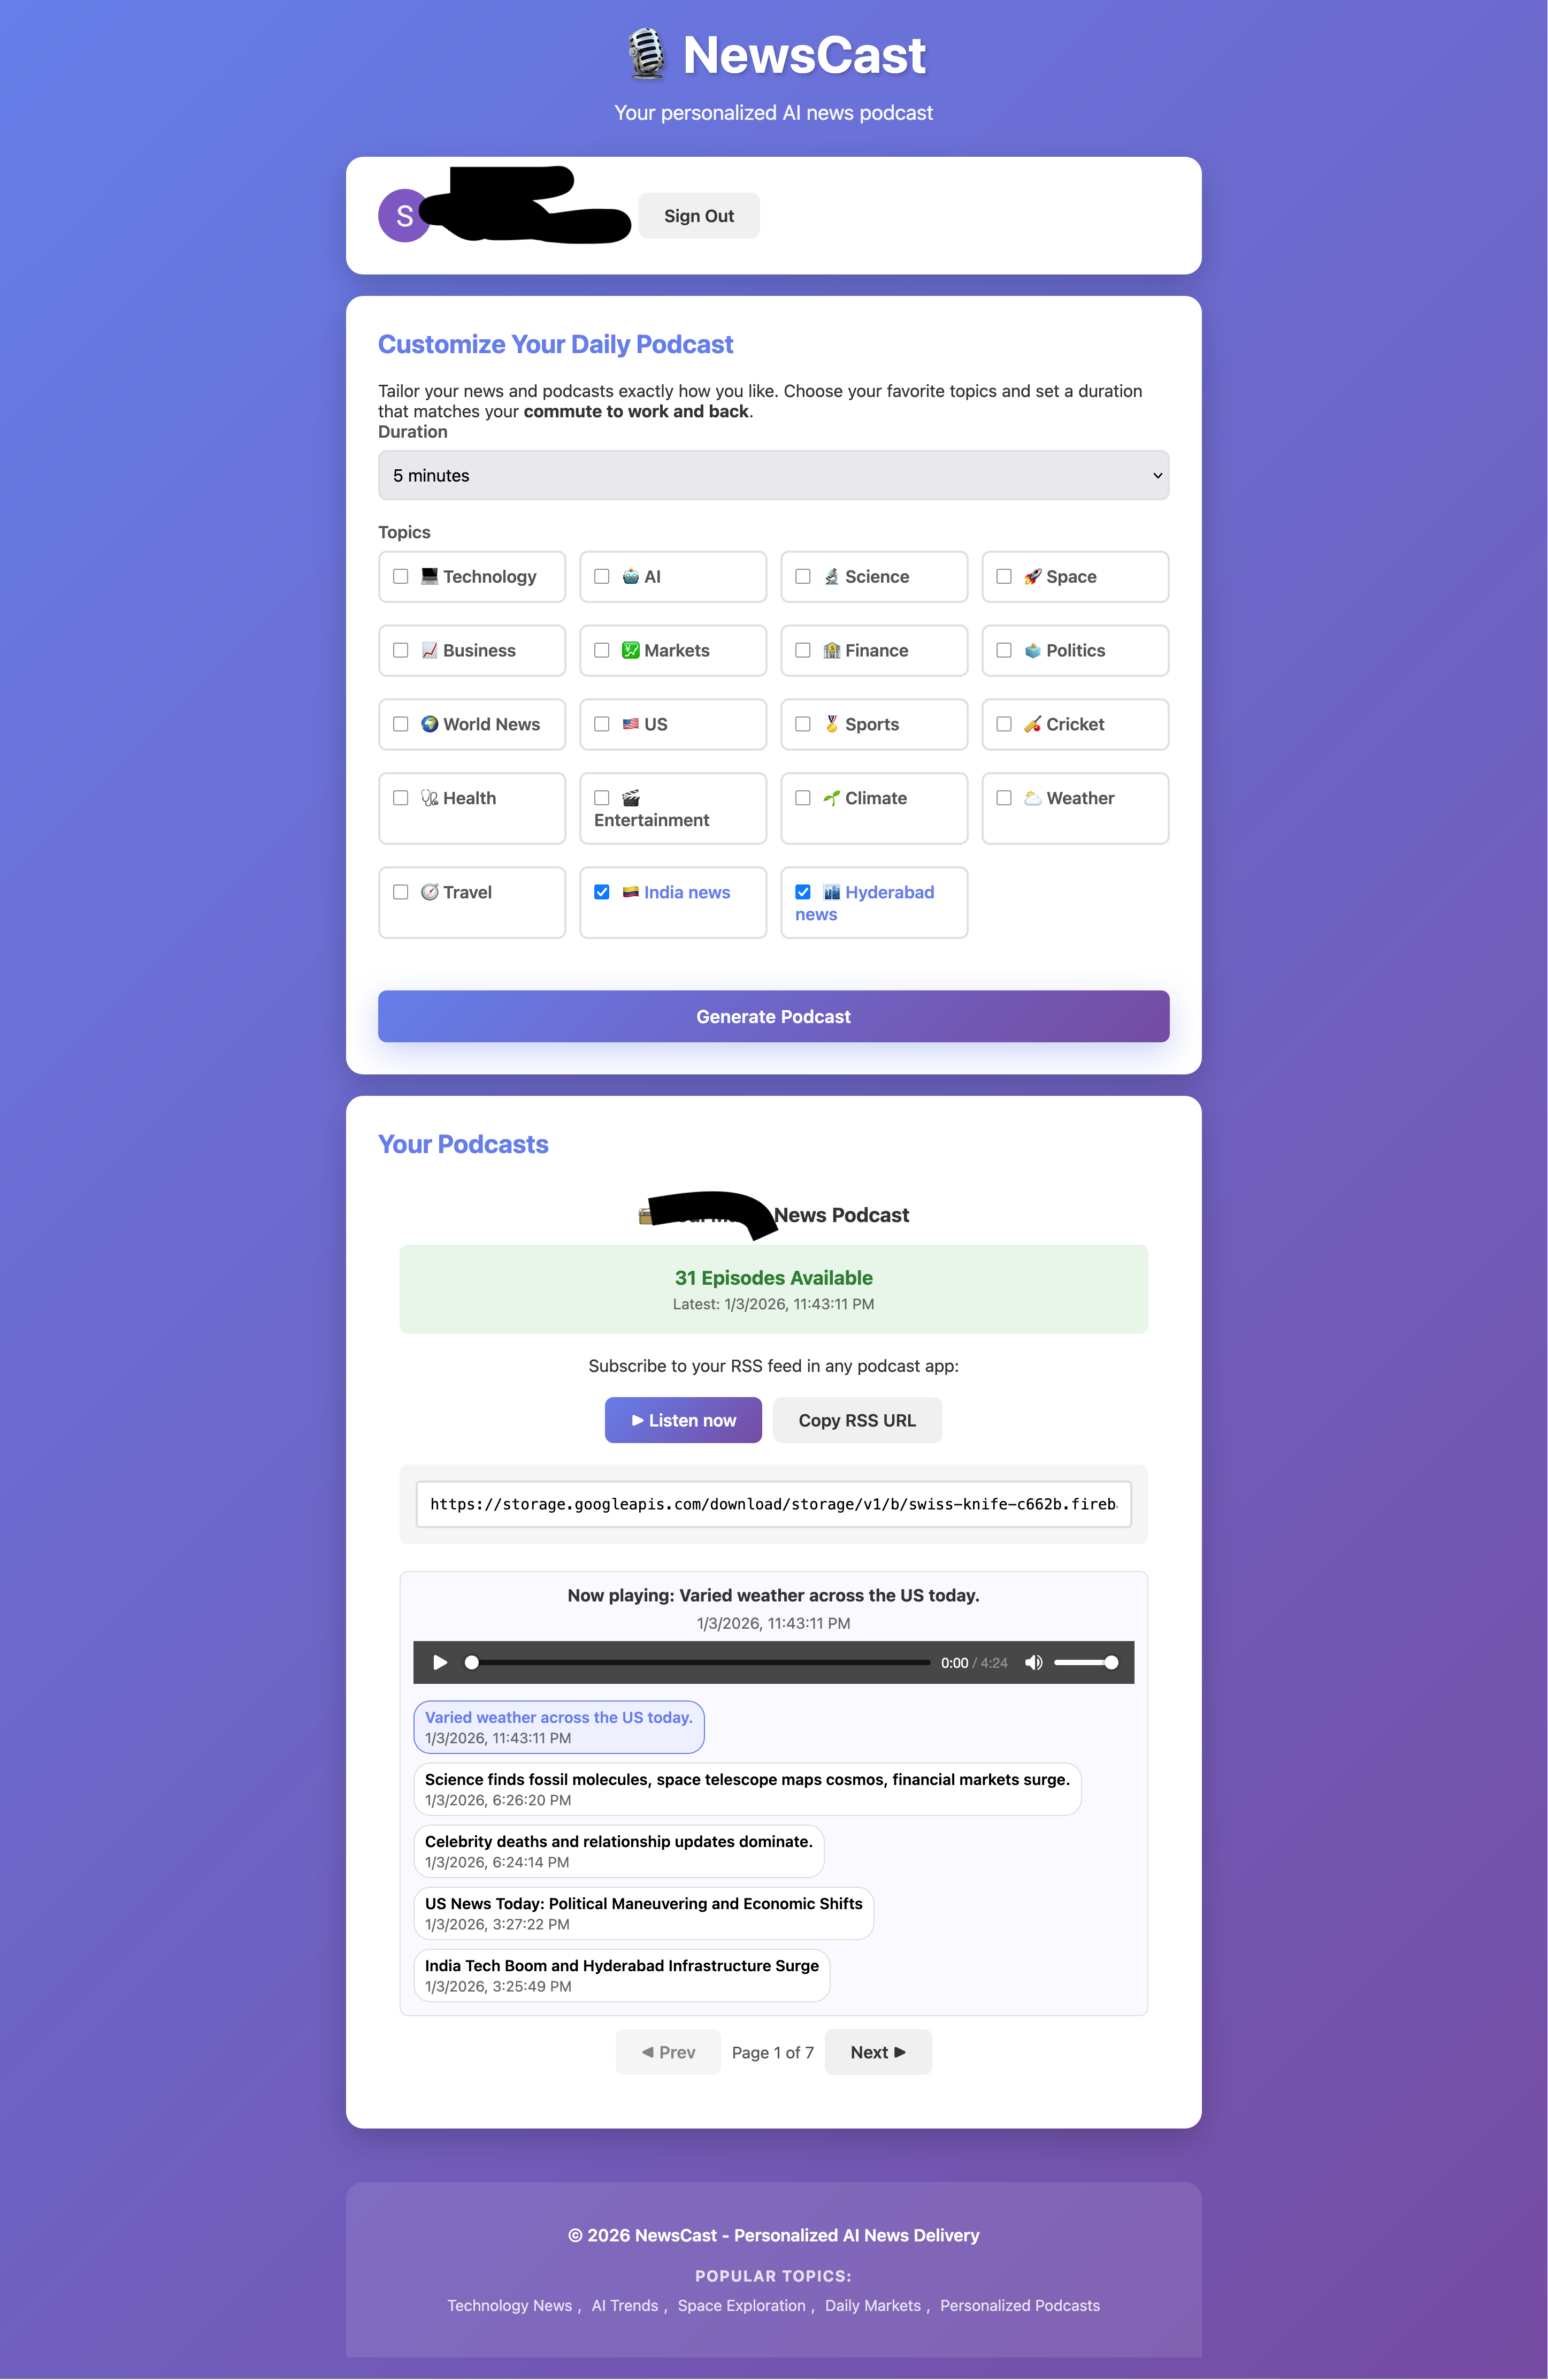
<p>Handwritten by me, with grammar and typos corrected by AI.</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><category term="Personal" /><category term="Reflections" /><summary type="html"><![CDATA[Twenty years ago today, I embarked on my first tech job. From Oracle Apps and Adobe Flex to GCP, Salesforce, and Microsoft, here is a chronological reflection of my 20-year career, the lessons learned, and the evolution of tech. Read more...]]></summary></entry><entry><title type="html">Vibecoding Over The Weekend - Building Apps with AI Agents</title><link href="https://www.neilghosh.com/2026/01/vibecoding-over-the-weekend.html" rel="alternate" type="text/html" title="Vibecoding Over The Weekend - Building Apps with AI Agents" /><published>2026-01-04T00:00:00+00:00</published><updated>2026-01-04T00:00:00+00:00</updated><id>https://www.neilghosh.com/2026/01/vibecoding-over-the-weekend</id><content type="html" xml:base="https://www.neilghosh.com/2026/01/vibecoding-over-the-weekend.html"><![CDATA[<p>Over the weekend, I decided to dive into some coding projects that had been on my mind for quite a while. I wanted to experiment with a few ideas that I believed could enhance my workflow and overall coding experience. The first one was having a one-stop landing page for various astronomical events like sunrise and sunset times, moon phases, and other celestial occurrences. Also wanted to keep track of Indian calendar details like zodiac signs. The second one was to create a personalized news podcast that curates news based on my interests and reads them out loud. I wrote about the mechanism earlier in <a href="https://medium.com/google-cloud/make-your-own-podcast-with-gemini-0fc7a191fbb7">Medium</a>. Now I wanted to productize it.</p>

<h2 id="lets-look-at-the-process">Let’s Look at the Process</h2>

<p>For the astronomical landing page, the first thing I did was get a good subdomain name. Firebase gives out .web.app subdomains so the choice of hosting was easy. It’s just a static site (for now) so the entire logic is in JavaScript. I used Antigravity for coding and let it run in “Fast mode” and occasionally just approved commands. It by default gave a mobile-friendly page which I am ok with because people mostly would launch this on mobile.</p>

<p>Initially the prompt was something very basic like “Create a landing page that shows astronomical events like sunrise and sunset times, moon phases, and other celestial occurrences. Also include Indian calendar details like zodiac signs.” This was a good start but had a lot of numbers on the page. I wanted more visual indicators like a progress bar showing things like how far the day or night has progressed before the next sunrise or sunset.</p>

<p><img src="/assets/2026/stargazing-web-app-screenshot.png" alt="Stargazing Web App Interface" /></p>

<p>The good thing about Antigravity was that it can fire up the Chrome agent and launch the app locally and take a screenshot to check if it has implemented correctly and iterate if required. While iterating I realized occasionally it breaks the working functionality while implementing new things. For example, while implementing the planetary chart it ended up messing up the embedded sky chart. So I decided to create a snapshot of features using markdown file based on the current feature (especially describing the functional UI components like progress bars and the start and end time). This markdown file could just be my reference to the coding agent for regression testing and make sure they always keep working when new features are added.</p>

<h2 id="the-good-and-bad">The Good and Bad</h2>

<p>While I am really glad that I could implement it in a matter of 5 hours, I think at the same time I feel I am not aware of the code structure and where to fix minor bug fixes if needed (without any AI tool help). It’s less likely I will have to do any changes without an AI coding tool’s help. It’s just I am not sure how maintainable this code would be in the long run. I guess I will have to wait and see how it goes.</p>

<p>For example, I wanted the sky map to be zoomable but Antigravity wasn’t able to implement it, though I gave a lot of feedback over and over. It just implemented the wheel scroll event and plus/minus buttons which don’t work because when you scroll the wheel the entire page scrolls. Even it could not implement the multi-touch way of being able to zoom on a touch device like mobile. I know with correct guidance it would be able to implement correctly eventually, but the problem is I don’t know much about the exact code where these JS components are implemented in the codebase so that I could give the context to the coding agent like tagging the exact file and function name.</p>

<p>This is a drawback I think for the future where we are getting super dependent on autonomous agents. This was not really a problem when we copied and pasted code from the chat window, at least the code was in our visual range and our brain could recall it. Possibly I should give it a prompt such that it generates an architecture diagram going through the current implementation and I try to understand it by going through it.</p>

<h2 id="running-out-of-quota">Running Out of Quota</h2>

<p>The second biggest issue was that I ran out of quota for Antigravity. I had to wait for the quota to reset on Monday morning to continue working on the news podcast app.</p>

<blockquote class="twitter-tweet"><p lang="en" dir="ltr">Now what <a href="https://t.co/nMXUx0kPkB">pic.twitter.com/nMXUx0kPkB</a></p>&mdash; Neil Ghosh (@neilghosh) <a href="https://twitter.com/neilghosh/status/2007366009938919692?ref_src=twsrc%5Etfw">January 3, 2026</a></blockquote>
<script async="" src="https://platform.twitter.com/widgets.js" charset="utf-8"></script>

<p>So I moved to good old GitHub Copilot where I happen to have a very large quota (if not unlimited). It’s good but I won’t have the browser agent so I would mostly give the feedback manually by looking at the rendered UI. Also the news podcast app was a bit complex instead of simply a client UI. I have a few services running in cloud functions written in Python and a JS client calling them. It has authentication implemented and CORS handling. So simulating all this locally with emulator was difficult (which is the right thing to do for quicker iteration), so I mostly relied on re-deployment in the cloud. While the Firebase site hosting was quick to be redeployed, deploying Gen 2 cloud functions was time consuming (although multiple functions were deployed in parallel). So the iteration cycle was a bit slow.</p>

<p>At some point I did get the Antigravity quota reset (even using a different model gives you some more time with Antigravity) but the browser agent quota was still not available.</p>

<blockquote class="twitter-tweet"><p lang="en" dir="ltr">How do people automatically push feedback (and update instructions for future improvement) from autonomous agents every time they fail or take too long to execute?<br /><br />This should definitely be easier than traditional systems that require source-code changes with correct syntax.</p>&mdash; Neil Ghosh (@neilghosh) <a href="https://twitter.com/neilghosh/status/2007068070326714466?ref_src=twsrc%5Etfw">January 2, 2026</a></blockquote>
<script async="" src="https://platform.twitter.com/widgets.js" charset="utf-8"></script>

<h2 id="what-i-learned">What I Learned</h2>

<p>While creating the news podcast app I learned that it’s always better to let the AI agent itself write the prompt that we use in the runtime inside the app (while calling Gemini API to generate news transcript and audio). My handwritten prompt was not very efficient although the intent was clear. So it’s more efficient to give the AI agent the intent which creates the prompt which in turn is used in runtime to get AI API output.</p>

<p>This is why it’s also wise to generate the copilot-instructions.md file (or any other Agent.md file if you are using other tools like Claude Code) using Copilot itself just by giving the intent in your own version of English. Over a period of time, even to enhance the instruction file I give a prompt like “Summarize the learning from the current chat session and update the instructions file such that it can get the correct result in one shot next time. Examples should be generalized and not specific to the task in hand.” This “upserts” the new instructions properly in the existing instructions file.</p>

<p>Sometimes I also issue the following prompt “Make the instructions file (add the file in context) concise and to the point by removing any redundant information.” This way the instruction file does not bloat over a period of time.</p>

<p><img src="/assets/2026/news-podcast-app-screenshot.png" alt="News Podcast App Interface" /></p>

<h2 id="what-i-want-for-the-future">What I Want for the Future</h2>

<p>Ultimately, though I got good results, I would like to “engineer” these kinds of development tasks using autonomous agents instead of random back and forth in the chat window. When I say “engineer”, I mean there has to be a proper process to provide the initial intent and generate a plan and try to visualize what it would make and then create the first version say “pre-MVP” and there has to be a mechanism to provide persistent feedback and enhance the plan which would again automatically create the desired version and so on.</p>

<p>In this way since my requirements would always be built progressively it’s unlikely it will regress and also it would have a blueprint handy for a new engineer or even myself in the future to understand the code structure and be able to fix minor issues without much help from an AI coding agent.</p>

<p>Probably spec-driven development is the answer to this. More about this in another post when I explore more.</p>

<p>There were non-functional requirements like Google Analytics integration, SEO optimizations, dark mode etc which are common across projects, I could implement in one shot with minimal instructions. This gives developers time back to focus on building things which are unique to the app instead of spending time on plumbing work.</p>

<h2 id="try-the-apps">Try the Apps</h2>

<p>Do let me know your thoughts about the following:</p>

<ul>
  <li><strong>Stargazing App</strong>: <a href="https://stargazing.web.app">https://stargazing.web.app</a></li>
  <li><strong>News Podcast App</strong>: <a href="https://newscast.web.app">https://newscast.web.app</a></li>
</ul>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><category term="Programming" /><category term="AI Development" /><category term="Weekend Projects" /><summary type="html"><![CDATA[I tried implementing a couple of ideas I had in mind for a long time over the weekend using AI coding agents. Now I have mixed feelings about the results.]]></summary></entry><entry><title type="html">Run your own ChatGPT</title><link href="https://www.neilghosh.com/2025/12/run-your-own-ChatGPT.html" rel="alternate" type="text/html" title="Run your own ChatGPT" /><published>2025-12-28T00:00:00+00:00</published><updated>2025-12-28T00:00:00+00:00</updated><id>https://www.neilghosh.com/2025/12/run-your-own-ChatGPT</id><content type="html" xml:base="https://www.neilghosh.com/2025/12/run-your-own-ChatGPT.html"><![CDATA[<h1 id="run-your-own-chatgpt">Run your own ChatGPT</h1>

<p>Well the title is a bit click bait-y. It basically means running Large Language Models (LLMs) locally on your computer, even in a VM for that matter. Think of it as having your own personal AI assistant that runs entirely on your hardware, without sending any data to external servers.</p>

<p>There are two major advantages of running LLMs locally:</p>

<ul>
  <li>
    <p><strong>It’s free!</strong> You don’t have to pay for subscriptions like ChatGPT Plus ($20/month) or Gemini Pro. Once you download a model, you can use it as much as you want without any usage limits or API costs.</p>
  </li>
  <li>
    <p><strong>Privacy and Data Control</strong>: Though there are free versions of commercial LLMs, running on your own computer makes it completely private. You’re not giving away your personal queries, interests, and data to third-party servers. This is especially important if you’re asking health-related questions, working with confidential business data, or discussing sensitive topics.</p>
  </li>
</ul>

<p>Additionally, you get:</p>
<ul>
  <li><strong>No internet dependency</strong>: Once models are downloaded, you can use them offline</li>
  <li><strong>Customization</strong>: You can fine-tune models for specific tasks</li>
  <li><strong>No rate limits</strong>: Use the model as much as you want without throttling</li>
</ul>

<h2 id="setting-up-ollama">Setting up Ollama</h2>

<p>Firstly, you need to install and start <code class="language-plaintext highlighter-rouge">ollama</code>. <a href="https://ollama.com/download">Ollama</a> is a tool that simplifies running LLMs locally. It handles model management, provides a simple API, and optimizes model execution for your hardware.</p>

<p>On Mac, you can install it using Homebrew:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>brew <span class="nb">install </span>ollama
</code></pre></div></div>

<p>For Linux:</p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-fsSL</span> https://ollama.com/install.sh | sh
</code></pre></div></div>

<p>For Windows, download the installer from the Ollama website.</p>

<p>Next, we need to start the Ollama server. This runs in the background and handles all model inference requests:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ollama serve
</code></pre></div></div>

<p>The server will start on <code class="language-plaintext highlighter-rouge">http://localhost:11434</code> by default. Keep this terminal window open as it needs to run continuously.</p>

<h2 id="choosing-and-running-a-model">Choosing and Running a Model</h2>

<p>Now we need to decide which model to download. The model choice depends on your hardware capabilities:</p>

<ul>
  <li><strong>Small models (2B-7B parameters)</strong>: Run on most laptops, faster responses, less capable</li>
  <li><strong>Medium models (13B-30B parameters)</strong>: Need 16GB+ RAM, good balance of speed and quality</li>
  <li><strong>Large models (70B+ parameters)</strong>: Need 64GB+ RAM, best quality, slower</li>
</ul>

<p>I chose to run a very large model from Google’s Gemma family (<code class="language-plaintext highlighter-rouge">gemma3:27b</code> with 27 billion parameters) because I have a powerful machine - a Mac Studio with M2 Ultra chip and 128GB unified memory. The “27b” in the model name indicates it has 27 billion parameters.</p>

<p><strong>Note</strong>: Each billion parameters roughly needs 2GB of RAM when loaded. So a 27B model needs about 54GB of available RAM to run smoothly.</p>

<p>Open a new terminal (keep the <code class="language-plaintext highlighter-rouge">ollama serve</code> running in the first one) and run:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ollama run gemma3:27b
</code></pre></div></div>

<p>For the first time, depending on the model size, it will download the model files (this can take several minutes for large models). Once downloaded, you’ll see:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt;&gt;&gt; Send a message (/? for help)
</code></pre></div></div>

<h2 id="testing-the-model">Testing the Model</h2>

<p>Now you can chat with the model directly in the terminal:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt;&gt;&gt; Who are you? Whats todays date
Hi there! I'm Gemma, an open-weights AI assistant. I'm a large language model trained by Google DeepMind. The Gemma team are my creators.

Today is November 21, 2023.
</code></pre></div></div>

<p><strong>Important</strong>: The date is much in the past because the model was trained around that time. LLMs don’t have real-time information - they only know what was in their training data. The model’s knowledge is frozen at its training cutoff date, and it cannot learn or update itself with new information without retraining.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt;&gt;&gt; What's your knowledge cut off and Parameters?
My knowledge cut-off is **September 2021**. This means I don't have information about events that occurred after that date. So, I won't know about things that happened in 2022, 2023, or beyond unless specifically included in my training data.

As for my parameters, I come in two sizes:

*   **Gemma 2B:** Has **2 billion parameters**. This is a smaller, faster model suitable for resource-constrained environments.
*   **Gemma 7B:** Has **7 billion parameters**. This is a larger, more capable model that generally delivers better performance.

I'm the open-weights version, meaning the model weights are publicly available! You can find more details on the Gemma models here: [https://ai.google.dev/gemma](https://ai.google.dev/gemma)
</code></pre></div></div>

<p><strong>Understanding Parameters</strong>: The number of parameters (weights) in a neural network directly correlates with its capability to understand and generate text. More parameters generally mean better understanding of context, nuance, and ability to generate higher quality responses, but at the cost of more memory and slower inference.</p>

<p>Let’s test its knowledge of recent developments:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt;&gt;&gt; What's an MCP server
An MCP server refers to a server used for playing **Minecraft: Pocket Edition (MCPE)** using a third-party server software called **Multiplayer for Pocket Edition (MCPC)**, or sometimes just "MCP." Here's a breakdown of what it is and why it's different from
regular Minecraft servers:
</code></pre></div></div>

<p>As you can see, it doesn’t know that “MCP Server” now refers to the <strong>Model Context Protocol</strong> - a new standard introduced by Anthropic in late 2024 that has become a hot topic in the AI space. This clearly demonstrates the model’s knowledge cutoff limitation.</p>

<p>Despite this limitation, the model is still very powerful for:</p>
<ul>
  <li>General knowledge questions (up to its training date)</li>
  <li>Coding and programming help</li>
  <li>Writing and content creation</li>
  <li>Analysis and reasoning tasks</li>
  <li>Mathematical calculations</li>
</ul>

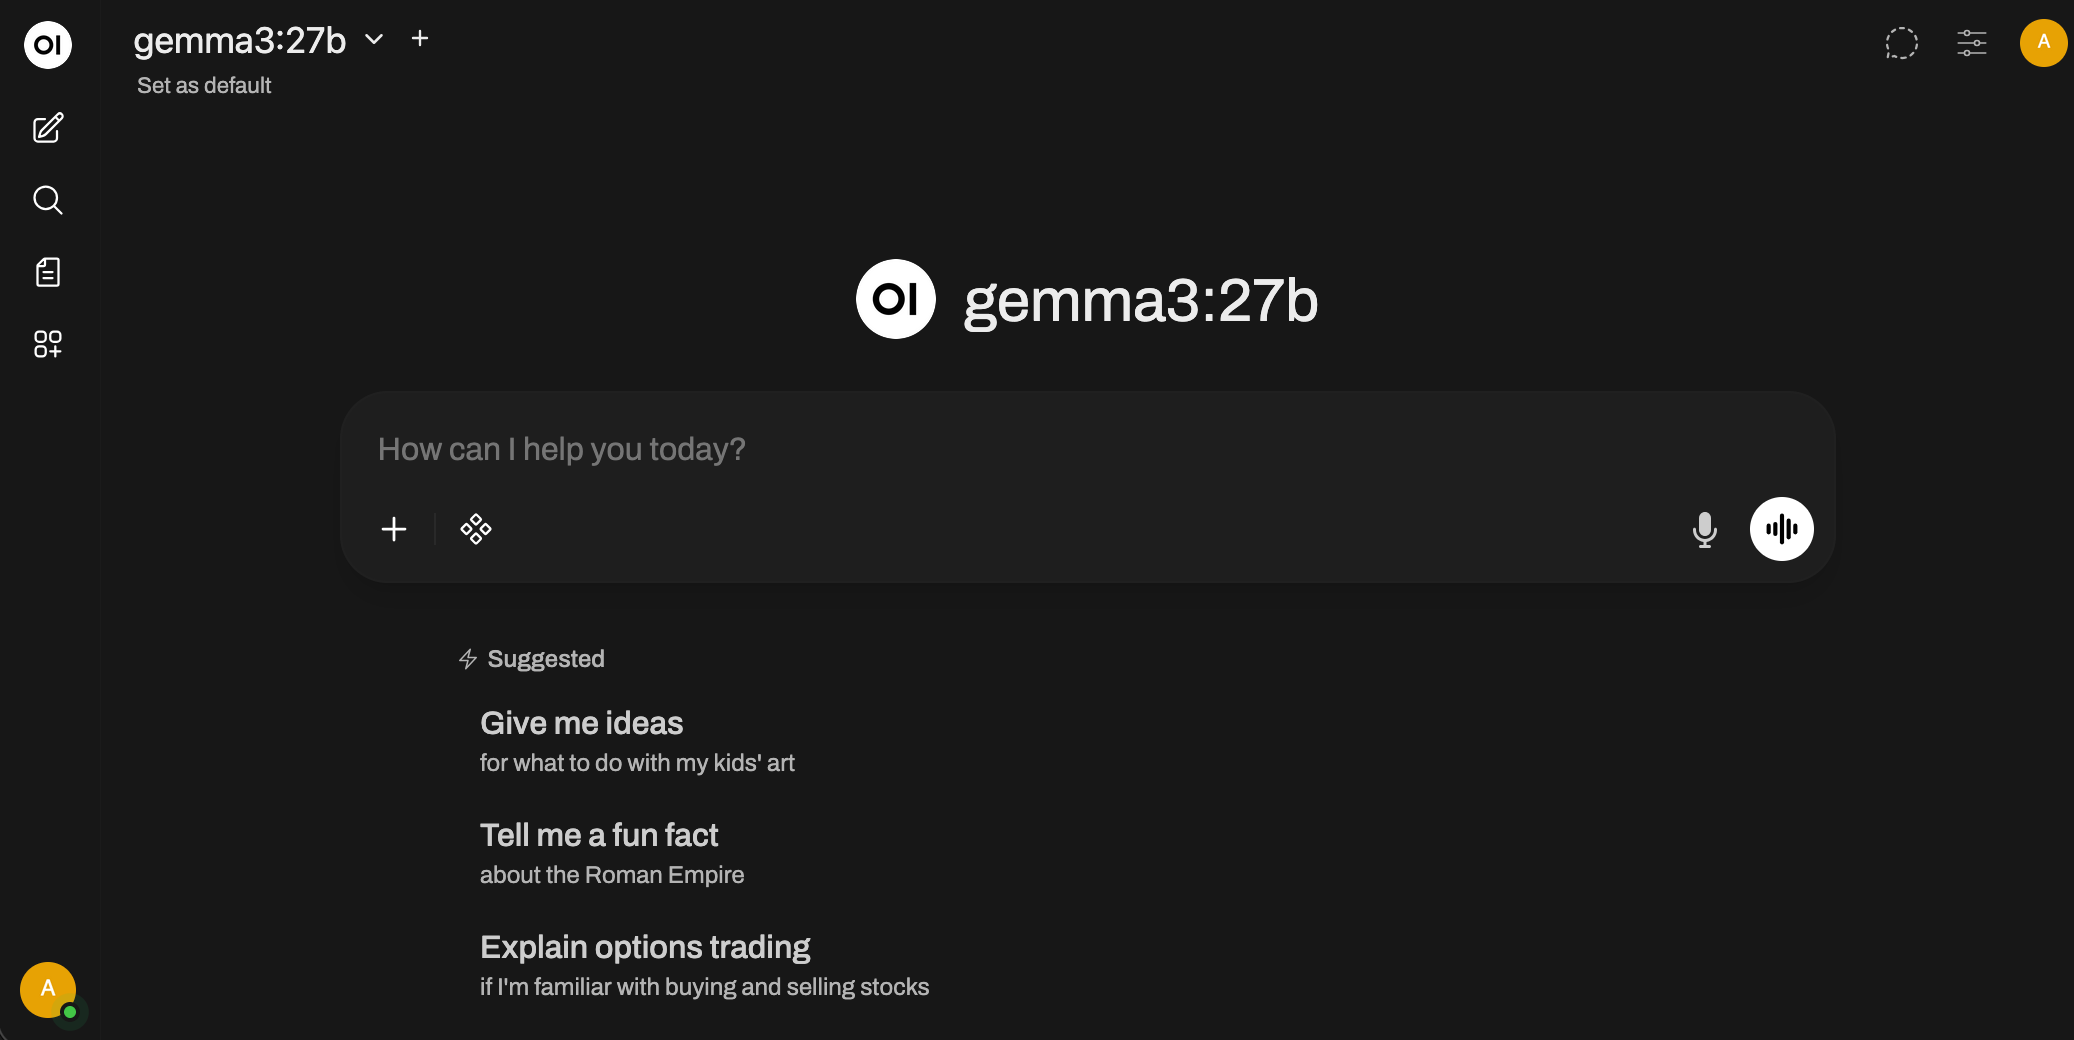
<h2 id="adding-a-web-interface-with-open-webui">Adding a Web Interface with Open WebUI</h2>

<p>While the terminal interface works great, you might prefer a more user-friendly ChatGPT/Gemini-style chat interface in your browser. That’s where <a href="https://openwebui.com/">Open WebUI</a> comes in - it’s an open-source, self-hosted web interface that connects to Ollama.</p>

<p>To run Open WebUI, you need Docker Desktop installed, though there are also Python-based installation methods available.</p>

<p>If you have Docker Desktop running, execute this command:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker run <span class="nt">-d</span> <span class="nt">-p</span> 3000:8080 <span class="nt">--add-host</span><span class="o">=</span>host.docker.internal:host-gateway <span class="nt">-v</span> open-webui:/app/backend/data <span class="nt">--name</span> open-webui <span class="nt">--restart</span> always ghcr.io/open-webui/open-webui:main
</code></pre></div></div>

<p><strong>What this command does</strong>:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">-d</code>: Runs the container in detached mode (background)</li>
  <li><code class="language-plaintext highlighter-rouge">-p 3000:8080</code>: Maps port 8080 in the container to port 3000 on your host</li>
  <li><code class="language-plaintext highlighter-rouge">--add-host=host.docker.internal:host-gateway</code>: Allows the Docker container to communicate with Ollama running on your host</li>
  <li><code class="language-plaintext highlighter-rouge">-v open-webui:/app/backend/data</code>: Creates a persistent volume for chat history and settings</li>
  <li><code class="language-plaintext highlighter-rouge">--restart always</code>: Automatically restart the container if it crashes or after system reboot</li>
</ul>

<p>Once the Docker container is running, open your browser and navigate to http://localhost:3000/</p>

<p><img src="/assets/2025/ollama-open-webui.png" alt="Open WebUI Interface" /></p>

<h2 id="using-the-ollama-api">Using the Ollama API</h2>

<p>You can also interact with Ollama programmatically using its REST API. This is useful for integrating LLMs into your own applications:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl http://localhost:11434/api/generate <span class="nt">-d</span> <span class="s1">'{
  "model": "gemma3:27b",
  "prompt":"Who was first President of India"
}'</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>neilghosh@neilghosh-mac-studio ~ % curl http://localhost:11434/api/generate -d '{  "model": "gemma3:27b",   "prompt":"Who was first President of India"}'
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:47.941022Z","response":"The","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:47.980486Z","response":" first","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.019804Z","response":" President","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.059296Z","response":" of","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.098868Z","response":" India","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.138344Z","response":" was","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.177787Z","response":" **","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.217355Z","response":"Dr","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.25691Z","response":".","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.296326Z","response":" Raj","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.335835Z","response":"endra","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:48.375877Z","response":" Prasad","done":false}
...
...
Indian","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:50.230835Z","response":" Constitution","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:50.27012Z","response":".","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:50.309673Z","response":"\n\n\n\n","done":false}
{"model":"gemma3:27b","created_at":"2025-12-28T11:43:50.34898Z","response":"","done":true,"done_reason":"stop","context":[105,2364,107,15938,691,1171,5376,529,4673,106,107,105,4368,107,818,1171,5376,529,4673,691,5213,9231,236761,15105,37888,91520,84750,236743,108,2209,7779,699,236743,236770,236819,236810,236771,531,236743,236770,236819,236825,236778,236764,1646,16492,10911,236761,1293,691,496,2307,8575,528,506,6225,21555,7296,1680,4673,16531,21555,236764,532,6657,496,3629,3853,528,66582,506,6225,20901,236761,110],"total_duration":2903714459,"load_duration":156688500,"prompt_eval_count":15,"prompt_eval_duration":337553125,"eval_count":62,"eval_duration":2382672126}
</code></pre></div></div>

<h2 id="understanding-token-streaming">Understanding Token Streaming</h2>

<p>The responses come in small chunks because of the fundamental nature of how LLMs work. The model generates and streams back one <strong>token</strong> at a time (a token is roughly a word or part of a word). This isn’t just a fancy UI effect to make it look like it’s “thinking” - it’s actually how the model generates text:</p>

<ol>
  <li>The model predicts the most likely next token based on all previous tokens</li>
  <li>That token is sent to the client immediately (streaming)</li>
  <li>The model then uses that token as input to predict the next token</li>
  <li>This process repeats until the model decides to stop</li>
</ol>

<p>This is why you see the <code class="language-plaintext highlighter-rouge">"done":false</code> in each JSON response until the final one. Streaming allows users to start reading the response before generation is complete, which is especially valuable for long responses.</p>

<h2 id="specialized-models-for-different-tasks">Specialized Models for Different Tasks</h2>

<p>While Gemma3:27b is a powerful general-purpose LLM, there are specialized models optimized for specific tasks. For coding and programming tasks, <code class="language-plaintext highlighter-rouge">qwen2.5-coder:32b</code> is excellent.</p>

<p><strong>Qwen2.5-Coder</strong> is specifically trained on massive amounts of code and technical documentation, making it particularly good at:</p>
<ul>
  <li>Code generation and completion</li>
  <li>Debugging and code review</li>
  <li>Explaining code</li>
  <li>Converting between programming languages</li>
  <li>Writing documentation</li>
</ul>

<p>To run it:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ollama run qwen2.5-coder:32b
</code></pre></div></div>

<p>Other popular models available through Ollama:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">llama3.1:70b</code> - Meta’s flagship open model</li>
  <li><code class="language-plaintext highlighter-rouge">deepseek-coder:33b</code> - Another excellent coding model</li>
  <li><code class="language-plaintext highlighter-rouge">mistral:7b</code> - Fast and efficient general-purpose model</li>
  <li><code class="language-plaintext highlighter-rouge">codellama:34b</code> - Meta’s specialized code model</li>
</ul>

<h2 id="integrating-with-vs-code-using-continue">Integrating with VS Code using Continue</h2>

<p>To use these local models directly in VS Code (similar to GitHub Copilot or other AI coding assistants), you can install the <strong>Continue</strong> extension. This brings the power of local LLMs right into your editor with features like:</p>

<ul>
  <li><strong>Chat interface</strong>: Ask coding questions in a sidebar</li>
  <li><strong>Code editing</strong>: Select code and ask the AI to modify it</li>
  <li><strong>Autocomplete</strong>: Get inline code suggestions as you type</li>
  <li><strong>Code explanation</strong>: Understand complex code</li>
</ul>

<p>Install Continue from the VS Code marketplace, then configure it to use your local Ollama models by editing its config file (<code class="language-plaintext highlighter-rouge">~/.continue/config.json</code>):</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">name</span><span class="pi">:</span> <span class="s">Local Config</span>
<span class="na">version</span><span class="pi">:</span> <span class="s">1.0.0</span>
<span class="na">schema</span><span class="pi">:</span> <span class="s">v1</span>
<span class="na">models</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Qwen3 30B</span>
    <span class="na">provider</span><span class="pi">:</span> <span class="s">ollama</span>
    <span class="na">model</span><span class="pi">:</span> <span class="s">qwen3:30b</span>
    <span class="na">roles</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">chat</span>
      <span class="pi">-</span> <span class="s">edit</span>
      <span class="pi">-</span> <span class="s">apply</span>      
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">qwen2.5-coder:32b</span>
    <span class="na">provider</span><span class="pi">:</span> <span class="s">ollama</span>
    <span class="na">model</span><span class="pi">:</span> <span class="s">qwen2.5-coder:32b</span>
    <span class="na">roles</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">autocomplete</span>
</code></pre></div></div>

<p><strong>Understanding the roles</strong>:</p>
<ul>
  <li><strong>chat</strong>: Used for the chat sidebar where you ask questions</li>
  <li><strong>edit</strong>: Used when you select code and ask the AI to modify it</li>
  <li><strong>apply</strong>: Used for applying changes suggested by the AI</li>
  <li><strong>autocomplete</strong>: Used for inline code completion as you type</li>
</ul>

<p>The configuration above uses the larger Qwen3 30B for interactive tasks (chat, edit, apply) where quality matters, and the specialized qwen2.5-coder for fast autocomplete suggestions.</p>

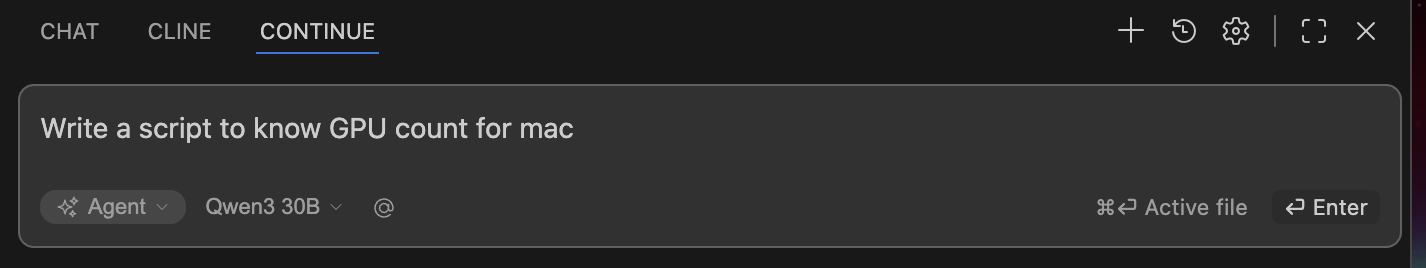
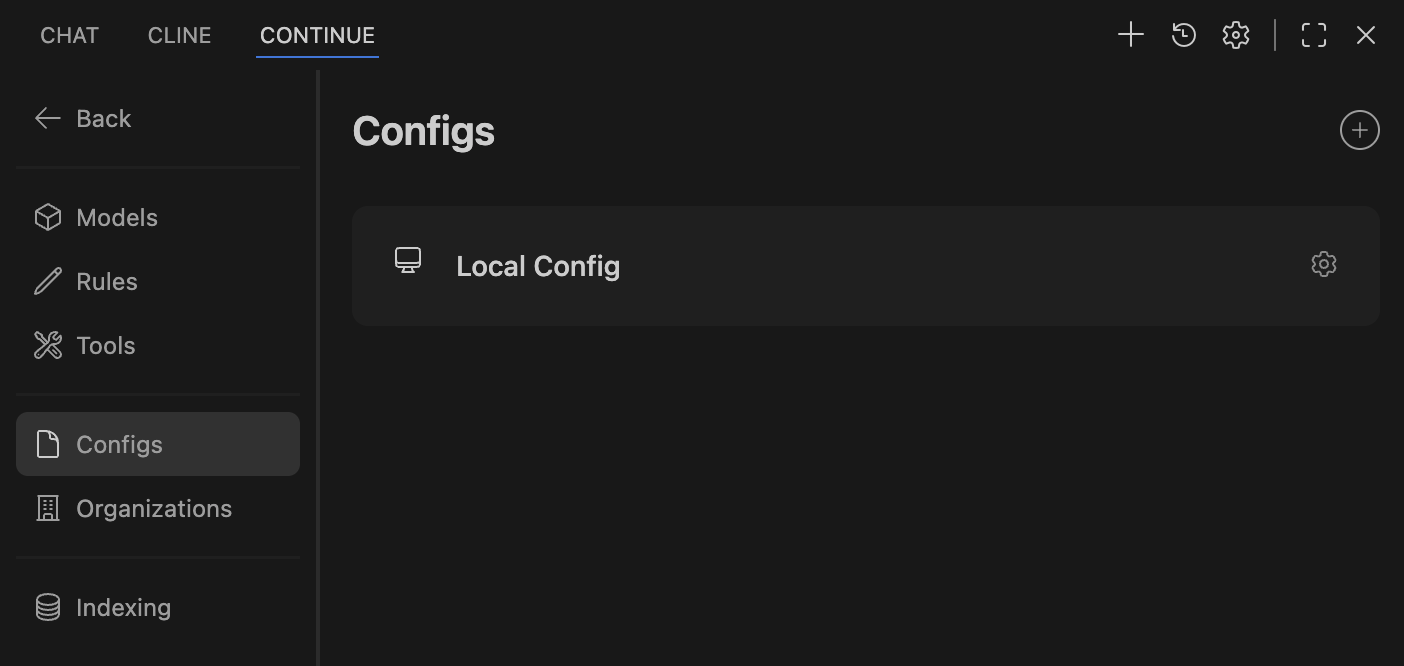
<p><img src="/assets/2025/vscode-continue-chat.png" alt="Continue Chat in VS Code" /></p>

<p>If you see it asking for API keys of subscription-based services, double-check that local config is properly enabled in the Continue plugin settings.</p>

<p><img src="/assets/2025/vscode-continue-config.png" alt="Continue Plugin Configuration" /></p>

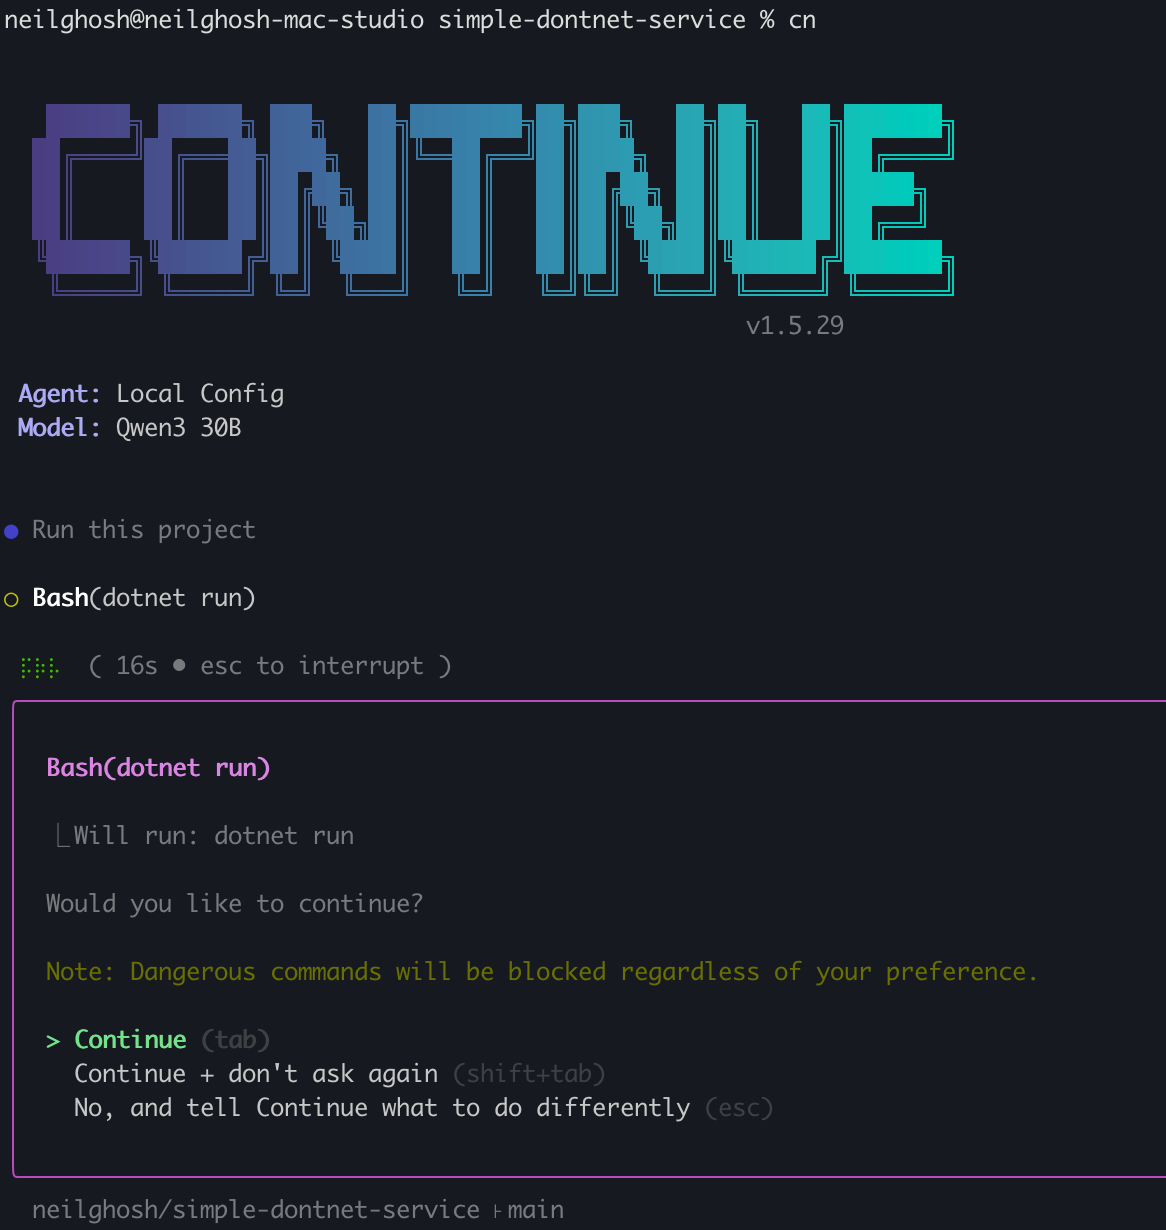
<h2 id="continue-cli-for-terminal-users">Continue CLI for Terminal Users</h2>

<p>For developers who prefer working in the terminal, Continue also offers a CLI tool that functions like GitHub Copilot CLI or Gemini CLI. It allows you to ask coding questions and get AI assistance directly in your terminal:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npm <span class="nb">install</span> <span class="nt">-g</span> @continuedev/cli
</code></pre></div></div>

<p>After installation, you can use commands like:</p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">continue</span> <span class="s2">"how do I parse JSON in Python"</span>
<span class="k">continue</span> <span class="s2">"explain this error: ModuleNotFoundError"</span>
<span class="k">continue</span> <span class="s2">"write a function to sort an array"</span>
</code></pre></div></div>

<p><img src="/assets/2025/continue-cli-terminal.png" alt="Continue CLI in Terminal" /></p>

<h2 id="managing-models">Managing Models</h2>

<p>You can list all models that are downloaded on your system at any time:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ollama list
</code></pre></div></div>

<p>Output:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>NAME                 ID              SIZE     MODIFIED
deepseek-r1:32b      edba8017331d    19 GB    45 hours ago
qwen3:30b            ad815644918f    18 GB    2 days ago
qwen2.5-coder:32b    b92d6a0bd47e    19 GB    2 days ago
gemma3:27b           a418f5838eaf    17 GB    2 days ago
</code></pre></div></div>

<p>This shows all downloaded models, their IDs, disk space usage, and when they were last used.</p>

<p><strong>Useful Ollama commands</strong>:</p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ollama ps                    <span class="c"># Show currently running models</span>
ollama pull &lt;model&gt;          <span class="c"># Download a model</span>
ollama <span class="nb">rm</span> &lt;model&gt;            <span class="c"># Remove a model to free up space</span>
ollama show &lt;model&gt;          <span class="c"># Show model information and parameters</span>
ollama <span class="nb">cp</span> &lt;src&gt; &lt;dest&gt;       <span class="c"># Copy a model</span>
</code></pre></div></div>

<p><strong>Note</strong>: Models are automatically loaded into memory when you use them and unloaded after a period of inactivity to free up RAM. Use <code class="language-plaintext highlighter-rouge">ollama ps</code> to see which models are currently loaded in memory.</p>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>Running LLMs locally gives you privacy, cost savings, and complete control over your AI assistant. While local models may not be as capable as the latest GPT-4 or Claude models, they’re constantly improving and are more than sufficient for most everyday tasks. The ecosystem of tools like Ollama, Open WebUI, and Continue makes it easier than ever to get started with local AI.</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><category term="LLM" /><summary type="html"><![CDATA[Learn how to run large language models locally on your computer using Ollama, including Gemma, Qwen, and other models, with web UI and CLI options for privacy and cost-free AI assistance.]]></summary></entry><entry><title type="html">Secure your CI/CD with Secret less deployment</title><link href="https://www.neilghosh.com/2025/10/secure-your-cicd-with-secret-less-deployment.html" rel="alternate" type="text/html" title="Secure your CI/CD with Secret less deployment" /><published>2025-10-26T00:00:00+00:00</published><updated>2025-10-26T00:00:00+00:00</updated><id>https://www.neilghosh.com/2025/10/secure-your-cicd-with-secret-less-deployment</id><content type="html" xml:base="https://www.neilghosh.com/2025/10/secure-your-cicd-with-secret-less-deployment.html"><![CDATA[<h1 id="deploying-to-azure-without-storing-passwords-a-real-world-example">Deploying to Azure Without Storing Passwords: A Real-World Example</h1>

<p>I used to lose sleep over GitHub secrets. Every deployment credential stored in my repository felt like a ticking time bomb—what if someone accidentally logged it? What if my former colleague still had access to the org? What if the credentials leaked?</p>

<p>Then I discovered OIDC Federated Identity, and honestly, it changed how I think about CI/CD security.</p>

<p>Let me walk you through how we’re deploying a <code class="language-plaintext highlighter-rouge">.NET 8</code> API to Azure App Service without storing a single password, using a real application as our example.</p>

<hr />

<h2 id="the-problem-were-solving">The Problem We’re Solving</h2>

<p>Traditional deployment workflows look like this:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># The old way (please don't do this anymore)</span>
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Login to Azure</span>
  <span class="na">uses</span><span class="pi">:</span> <span class="s">azure/login@v2</span>
  <span class="na">with</span><span class="pi">:</span>
    <span class="na">creds</span><span class="pi">:</span> <span class="s">$</span>  <span class="c1"># This is a full JSON object with a password</span>
</code></pre></div></div>

<p>When you use <code class="language-plaintext highlighter-rouge">AZURE_CREDENTIALS</code>, you’re storing something that looks like this in your GitHub secrets:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"clientId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"abc123..."</span><span class="p">,</span><span class="w">
  </span><span class="nl">"clientSecret"</span><span class="p">:</span><span class="w"> </span><span class="s2">"super-secret-password-here"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"subscriptionId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"..."</span><span class="p">,</span><span class="w">
  </span><span class="nl">"tenantId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"..."</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>That <code class="language-plaintext highlighter-rouge">clientSecret</code> is the problem. It’s:</p>
<ul>
  <li><strong>Rotatable only by hand</strong> (easy to forget)</li>
  <li><strong>Visible in logs if leaked</strong> (one mistake and it’s compromised)</li>
  <li><strong>Active even when not needed</strong> (sitting there 24/7)</li>
</ul>

<h2 id="the-modern-solution-keyless-deployment-with-oidc">The Modern Solution: Keyless Deployment with OIDC</h2>

<p>Instead, GitHub can generate a short-lived token (OIDC token) that’s cryptographically signed with GitHub’s private key. Azure validates this signature and trusts the token automatically.</p>

<p>No passwords. No rotating credentials. Just a temporary, signed token that expires in minutes.</p>

<p>Here’s what we changed:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># The new way (keyless)</span>
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Log in to Azure using Managed Identity</span>
  <span class="na">uses</span><span class="pi">:</span> <span class="s">azure/login@v2</span>
  <span class="na">with</span><span class="pi">:</span>
    <span class="na">client-id</span><span class="pi">:</span> <span class="s">$</span>        <span class="c1"># Just an ID</span>
    <span class="na">tenant-id</span><span class="pi">:</span> <span class="s">$</span>        <span class="c1"># Just an ID</span>
    <span class="na">subscription-id</span><span class="pi">:</span> <span class="s">$</span>  <span class="c1"># Just an ID</span>
</code></pre></div></div>

<p>Notice the difference? We’re only storing IDs now. They’re not secrets—they’re public information that identifies <em>which</em> Azure resources and tenant we’re authenticating to. The actual authentication happens via OIDC token exchange.</p>

<hr />

<h2 id="our-real-application-a-simple-net-8-api">Our Real Application: A Simple .NET 8 API</h2>

<p>Let me introduce our test subject. It’s a straightforward ASP.NET Core Web API:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// Program.cs - Dependency injection setup</span>
<span class="kt">var</span> <span class="n">builder</span> <span class="p">=</span> <span class="n">WebApplication</span><span class="p">.</span><span class="nf">CreateBuilder</span><span class="p">(</span><span class="n">args</span><span class="p">);</span>

<span class="n">builder</span><span class="p">.</span><span class="n">Services</span><span class="p">.</span><span class="nf">AddControllers</span><span class="p">();</span>
<span class="n">builder</span><span class="p">.</span><span class="n">Services</span><span class="p">.</span><span class="n">AddScoped</span><span class="p">&lt;</span><span class="n">IIpAddressService</span><span class="p">,</span> <span class="n">OutboundIpService</span><span class="p">&gt;();</span>
<span class="n">builder</span><span class="p">.</span><span class="n">Services</span><span class="p">.</span><span class="n">AddScoped</span><span class="p">&lt;</span><span class="n">IIpifyProxy</span><span class="p">,</span> <span class="n">IpifyProxy</span><span class="p">&gt;();</span>
<span class="n">builder</span><span class="p">.</span><span class="n">Services</span><span class="p">.</span><span class="n">AddHttpClient</span><span class="p">&lt;</span><span class="n">IpifyProxy</span><span class="p">&gt;();</span>

<span class="kt">var</span> <span class="n">app</span> <span class="p">=</span> <span class="n">builder</span><span class="p">.</span><span class="nf">Build</span><span class="p">();</span>
<span class="n">app</span><span class="p">.</span><span class="nf">UseRouting</span><span class="p">();</span>
<span class="n">app</span><span class="p">.</span><span class="nf">MapControllers</span><span class="p">();</span>
<span class="n">app</span><span class="p">.</span><span class="nf">Run</span><span class="p">();</span>
</code></pre></div></div>

<p>It’s a layered architecture with services, proxies, and controllers. Nothing fancy. The kind of app you might be deploying yourself.</p>

<p>We containerize it with a multi-stage build:</p>

<div class="language-dockerfile highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Dockerfile - Multi-stage build for smaller image size</span>
<span class="k">FROM</span><span class="w"> </span><span class="s">mcr.microsoft.com/dotnet/sdk:8.0</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="s">build</span>
<span class="k">WORKDIR</span><span class="s"> /src</span>
<span class="k">COPY</span><span class="s"> simple-dotnet-service.csproj .</span>
<span class="k">RUN </span>dotnet restore
<span class="k">COPY</span><span class="s"> . .</span>
<span class="k">RUN </span>dotnet publish <span class="nt">-c</span> Release <span class="nt">-o</span> /app/publish simple-dotnet-service.csproj

<span class="k">FROM</span><span class="w"> </span><span class="s">mcr.microsoft.com/dotnet/aspnet:8.0</span><span class="w"> </span><span class="k">AS</span><span class="w"> </span><span class="s">runtime</span>
<span class="k">WORKDIR</span><span class="s"> /app</span>
<span class="k">COPY</span><span class="s"> --from=build /app/publish .</span>
<span class="k">ENV</span><span class="s"> ASPNETCORE_URLS=http://+:8080</span>
<span class="k">ENV</span><span class="s"> ASPNETCORE_ENVIRONMENT=Production</span>
<span class="k">EXPOSE</span><span class="s"> 8080</span>
<span class="k">ENTRYPOINT</span><span class="s"> ["dotnet", "SimpleDotnetService.dll"]</span>
</code></pre></div></div>

<p>This gets pushed to Azure Container Registry (ACR), then deployed to App Service.</p>

<hr />

<h2 id="how-the-workflow-actually-works">How the Workflow Actually Works</h2>

<p>Here’s our complete three-job deployment pipeline:</p>

<h3 id="job-1-build--test-no-azure-access-needed">Job 1: Build &amp; Test (No Azure Access Needed)</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">build-and-test</span><span class="pi">:</span>
  <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
  <span class="na">permissions</span><span class="pi">:</span>
    <span class="na">contents</span><span class="pi">:</span> <span class="s">read</span>
  
  <span class="na">steps</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Checkout code</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">actions/checkout@v4</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Setup .NET</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">actions/setup-dotnet@v4</span>
    <span class="na">with</span><span class="pi">:</span>
      <span class="na">dotnet-version</span><span class="pi">:</span> <span class="s1">'</span><span class="s">8.0.x'</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Restore dependencies</span>
    <span class="na">run</span><span class="pi">:</span> <span class="s">dotnet restore simple-dotnet-service.sln</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Build</span>
    <span class="na">run</span><span class="pi">:</span> <span class="s">dotnet build simple-dotnet-service.sln --configuration Release --no-restore</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Run tests</span>
    <span class="na">run</span><span class="pi">:</span> <span class="s">dotnet test simple-dotnet-service.sln --no-build --verbosity normal --configuration Release</span>
</code></pre></div></div>

<p>This runs on every push and PR. It doesn’t touch Azure at all. If the build fails, we stop before wasting time on Docker operations.</p>

<h3 id="job-2-build--push-docker-oidc-magic-happens-here">Job 2: Build &amp; Push Docker (OIDC Magic Happens Here)</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">build-and-push-docker</span><span class="pi">:</span>
  <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
  <span class="na">needs</span><span class="pi">:</span> <span class="s">build-and-test</span>
  <span class="na">if</span><span class="pi">:</span> <span class="s">github.event_name == 'push' || github.event_name == 'workflow_dispatch'</span>
  <span class="na">permissions</span><span class="pi">:</span>
    <span class="na">contents</span><span class="pi">:</span> <span class="s">read</span>
    <span class="na">id-token</span><span class="pi">:</span> <span class="s">write</span>  <span class="c1"># ← This is the key! Allows GitHub to generate OIDC token</span>
  
  <span class="na">steps</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Log in to Azure using Managed Identity</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">azure/login@v2</span>
    <span class="na">with</span><span class="pi">:</span>
      <span class="na">client-id</span><span class="pi">:</span> <span class="s">$</span>
      <span class="na">tenant-id</span><span class="pi">:</span> <span class="s">$</span>
      <span class="na">subscription-id</span><span class="pi">:</span> <span class="s">$</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Log in to Azure Container Registry</span>
    <span class="na">run</span><span class="pi">:</span> <span class="s">az acr login --name simpledotnetregistry565</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Build and push Docker image to ACR</span>
    <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">docker build -t simpledotnetregistry565.azurecr.io/simple-dotnet-service:$ \</span>
                   <span class="s">-t simpledotnetregistry565.azurecr.io/simple-dotnet-service:latest .</span>
      <span class="s">docker push simpledotnetregistry565.azurecr.io/simple-dotnet-service:$</span>
      <span class="s">docker push simpledotnetregistry565.azurecr.io/simple-dotnet-service:latest</span>
</code></pre></div></div>

<p>Look at that <code class="language-plaintext highlighter-rouge">permissions</code> block. <code class="language-plaintext highlighter-rouge">id-token: write</code> tells GitHub Actions: “I need permission to generate an OIDC token for this job.”</p>

<p>Here’s what happens behind the scenes:</p>

<ol>
  <li>
    <p><strong>GitHub generates an OIDC token</strong> - This token is cryptographically signed with GitHub’s private key and contains information about the workflow (repo, branch, commit, etc.)</p>
  </li>
  <li>
    <p><strong>azure/login passes it to Azure</strong> - The <code class="language-plaintext highlighter-rouge">azure/login@v2</code> action receives the token and sends it to Microsoft Identity Platform</p>
  </li>
  <li>
    <p><strong>Azure validates the signature</strong> - Azure uses GitHub’s public key to verify the token is legitimate</p>
  </li>
  <li>
    <p><strong>Azure checks the federated credential</strong> - Azure verifies that this specific repo on this specific branch is allowed (we’ll set this up next)</p>
  </li>
  <li>
    <p><strong>Azure issues an access token</strong> - If everything checks out, Azure gives back a temporary access token</p>
  </li>
  <li>
    <p><strong>All subsequent <code class="language-plaintext highlighter-rouge">az</code> commands use that token</strong> - No passwords needed</p>
  </li>
</ol>

<p>The result? Your Docker image is securely pushed to ACR.</p>

<h3 id="job-3-deploy-to-app-service">Job 3: Deploy to App Service</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">deploy-to-app-service</span><span class="pi">:</span>
  <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
  <span class="na">needs</span><span class="pi">:</span> <span class="s">build-and-push-docker</span>
  <span class="na">if</span><span class="pi">:</span> <span class="s">github.event_name == 'push' || github.event_name == 'workflow_dispatch'</span>
  <span class="na">permissions</span><span class="pi">:</span>
    <span class="na">contents</span><span class="pi">:</span> <span class="s">read</span>
    <span class="na">id-token</span><span class="pi">:</span> <span class="s">write</span>
  
  <span class="na">steps</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Log in to Azure using Managed Identity</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">azure/login@v2</span>
    <span class="na">with</span><span class="pi">:</span>
      <span class="na">client-id</span><span class="pi">:</span> <span class="s">$</span>
      <span class="na">tenant-id</span><span class="pi">:</span> <span class="s">$</span>
      <span class="na">subscription-id</span><span class="pi">:</span> <span class="s">$</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Configure App Service to use container image</span>
    <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">az webapp config container set \</span>
        <span class="s">--name simple-dotnet-service \</span>
        <span class="s">--resource-group simple-dotnet-service-rg \</span>
        <span class="s">--container-image-name simpledotnetregistry565.azurecr.io/simple-dotnet-service:latest \</span>
        <span class="s">--container-registry-url https://simpledotnetregistry565.azurecr.io</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Enable Managed Identity for ACR access</span>
    <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">az webapp identity assign \</span>
        <span class="s">--name simple-dotnet-service \</span>
        <span class="s">--resource-group simple-dotnet-service-rg \</span>
        <span class="s">--identities [system]</span>
  
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Restart App Service</span>
    <span class="na">run</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">az webapp restart \</span>
        <span class="s">--name simple-dotnet-service \</span>
        <span class="s">--resource-group simple-dotnet-service-rg</span>
</code></pre></div></div>

<p>Same OIDC flow, fresh token for this job. Now we tell App Service:</p>
<ul>
  <li>“Here’s your container image”</li>
  <li>“Use Managed Identity to pull it from ACR”</li>
  <li>“Restart so you pick up the new version”</li>
</ul>

<hr />

<h2 id="the-one-time-setup-trusting-github-in-azure">The One-Time Setup: Trusting GitHub in Azure</h2>

<p>This is the magic part. In your Azure subscription, you create a <strong>Federated Credential</strong> that says: “Trust OIDC tokens from GitHub when they come from this specific repository on the main branch.”</p>

<h3 id="option-1-azure-portal-gui">Option 1: Azure Portal (GUI)</h3>

<ol>
  <li>Go to <strong>Azure Portal</strong> → Search for <strong>App registrations</strong></li>
  <li>Click your app registration</li>
  <li>Go to <strong>Certificates &amp; secrets</strong> (left sidebar)</li>
  <li>Click <strong>Add a credential</strong> → <strong>Federated credential</strong></li>
  <li>Choose scenario: <strong>GitHub Actions deploying Azure resources</strong></li>
  <li>Fill in:
    <ul>
      <li><strong>Organization</strong>: your-github-org</li>
      <li><strong>Repository</strong>: simple-dontnet-service</li>
      <li><strong>Entity type</strong>: Branch</li>
      <li><strong>Branch name</strong>: main</li>
    </ul>
  </li>
  <li>Click <strong>Add</strong></li>
</ol>

<h3 id="option-2-azure-cli-faster">Option 2: Azure CLI (Faster)</h3>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Get your app registration object ID</span>
<span class="nv">APP_OBJECT_ID</span><span class="o">=</span><span class="si">$(</span>az ad app list <span class="nt">--display-name</span> <span class="s2">"YourAppName"</span> <span class="nt">--query</span> <span class="s2">"[0].id"</span> <span class="nt">-o</span> tsv<span class="si">)</span>

<span class="c"># Create the federated credential</span>
az ad app federated-credential create <span class="se">\</span>
  <span class="nt">--id</span> <span class="nv">$APP_OBJECT_ID</span> <span class="se">\</span>
  <span class="nt">--parameters</span> <span class="s1">'{
    "name": "GitHub-Actions-simple-dotnet-service",
    "issuer": "https://token.actions.githubusercontent.com",
    "subject": "repo:your-org/simple-dontnet-service:ref:refs/heads/main",
    "audiences": ["api://AzureADTokenExchange"]
  }'</span>
</code></pre></div></div>

<p>That’s it. After this, GitHub can deploy your app without any additional secrets.</p>

<hr />

<h2 id="why-this-matters-security-wins">Why This Matters (Security Wins)</h2>

<p>Let me be specific about what we’ve gained:</p>

<h3 id="-old-way-problems">❌ Old Way Problems</h3>
<ul>
  <li>Password stored 24/7 in GitHub (compromise window is huge)</li>
  <li>Manual rotation required (easy to forget)</li>
  <li>Password visible if accidentally logged (one mistake ruins everything)</li>
  <li>Same credential used for weeks (compromise goes undetected longer)</li>
</ul>

<h3 id="-new-way-benefits">✅ New Way Benefits</h3>
<ul>
  <li><strong>No passwords stored</strong> - Just IDs, which are public information</li>
  <li><strong>Automatic token generation</strong> - New token every workflow run</li>
  <li><strong>Tokens expire in minutes</strong> - Compromise window is tiny</li>
  <li><strong>Tokens are signed</strong> - GitHub and Azure verify cryptographically</li>
  <li><strong>Audit trail</strong> - Exactly which repo ran which deployment when</li>
  <li><strong>Scope-limited</strong> - Token only works for this repo/branch combination</li>
</ul>

<hr />

<h2 id="visualizing-the-flow">Visualizing the Flow</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>GitHub Push
    ↓
build-and-test job (no Azure)
    ↓
build-and-push-docker job
    ├─ Generate OIDC token (GitHub private key)
    ├─ Send to Azure
    ├─ Azure validates (GitHub public key)
    ├─ Azure checks federated credential
    ├─ Azure issues access token
    ├─ Build Docker image
    └─ Push to ACR
    ↓
deploy-to-app-service job
    ├─ Generate fresh OIDC token
    ├─ Exchange for new access token
    ├─ Configure App Service
    ├─ Enable Managed Identity
    └─ Restart App Service
    ↓
Application running with new version
</code></pre></div></div>

<hr />

<h2 id="the-real-world-impact">The Real-World Impact</h2>

<p>I’ve been using this setup in production for months. Here’s what changed:</p>

<ol>
  <li><strong>I stopped checking if passwords were leaked</strong> - They don’t exist</li>
  <li><strong>Zero credential rotation overhead</strong> - It’s automatic</li>
  <li><strong>Better sleep at night</strong> - No late-night “did someone get my credentials?” anxiety</li>
  <li><strong>Cleaner audit logs</strong> - Every deployment is traceable to a specific commit</li>
  <li><strong>Easier for teams</strong> - New team members don’t need special secret management</li>
</ol>

<p>And honestly? It was simpler to set up than I expected. A few minutes in the Azure Portal, and we were done.</p>

<hr />

<h2 id="getting-started">Getting Started</h2>

<p>If you want to implement this yourself:</p>

<ol>
  <li><strong>Create or identify your Azure App Registration</strong> - You need the client ID</li>
  <li><strong>Get your tenant ID and subscription ID</strong> - These are in Azure Portal</li>
  <li><strong>Create the federated credential</strong> - Use the Portal or CLI command above</li>
  <li><strong>Add three GitHub secrets</strong>:
    <ul>
      <li><code class="language-plaintext highlighter-rouge">AZURE_CLIENT_ID</code></li>
      <li><code class="language-plaintext highlighter-rouge">AZURE_TENANT_ID</code></li>
      <li><code class="language-plaintext highlighter-rouge">AZURE_SUBSCRIPTION_ID</code></li>
    </ul>
  </li>
  <li><strong>Update your workflow</strong> - Use the <code class="language-plaintext highlighter-rouge">azure/login@v2</code> action with OIDC (add <code class="language-plaintext highlighter-rouge">id-token: write</code> permissions)</li>
  <li><strong>Delete old secrets</strong> - Like <code class="language-plaintext highlighter-rouge">AZURE_CREDENTIALS</code> or <code class="language-plaintext highlighter-rouge">REGISTRY_PASSWORD</code></li>
</ol>

<p>You can see the full workflow in our repository: <code class="language-plaintext highlighter-rouge">.github/workflows/azure-app-service-deploy.yml</code></p>

<hr />

<h2 id="what-about-other-platforms">What About Other Platforms?</h2>

<p>This pattern works with:</p>
<ul>
  <li><strong>AWS</strong> - OIDC provider, similar setup</li>
  <li><strong>GCP</strong> - Workload Identity Federation</li>
  <li><strong>HashiCorp Cloud</strong> - OIDC support</li>
  <li><strong>Any platform with OIDC support</strong> - The pattern is standardized</li>
</ul>

<hr />

<h2 id="final-thoughts">Final Thoughts</h2>

<p>Keyless deployment isn’t bleeding-edge anymore. It’s the sensible default. If you’re still storing full credentials in GitHub secrets, I’d encourage you to make the switch.</p>

<p>Your future self will thank you when you don’t have to panic about credential rotations at 2 AM.</p>

<hr />

<p><strong>Questions or running into issues?</strong> The <a href="https://learn.microsoft.com/en-us/azure/active-directory/workload-identities/workload-identity-federation">Azure documentation on OIDC</a> is excellent. Also check out <a href="https://docs.github.com/en/actions/deployment/security-hardening-your-deployments/about-security-hardening-with-openid-connect">GitHub’s official guide</a>.</p>

<p>Happy deploying! 🚀</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><category term="CI/CD" /><category term="Security" /><category term="DevOps" /><summary type="html"><![CDATA[Learn how to deploy to Azure without storing passwords using OIDC Federated Identity, eliminating the need for long-lived secrets in your CI/CD pipelines.]]></summary></entry><entry><title type="html">Moving to Medium. (For Now)</title><link href="https://www.neilghosh.com/2025/02/Moving-to-Medium.html" rel="alternate" type="text/html" title="Moving to Medium. (For Now)" /><published>2025-02-21T00:00:00+00:00</published><updated>2025-02-21T00:00:00+00:00</updated><id>https://www.neilghosh.com/2025/02/Moving-to-Medium</id><content type="html" xml:base="https://www.neilghosh.com/2025/02/Moving-to-Medium.html"><![CDATA[<p>I have decided to make the new posts in <a href="https://medium.com/@neilghosh">medium</a> which enables me to contribute to collection of community publications like <a href="https://medium.com/google-cloud">Google Cloud - Community</a>.
Here is my first post <a href="https://medium.com/google-cloud/bird-identification-with-gemini-api-c6af7cfc6532">Bird Identification With Gemini API</a>.</p>

<p>I could also put a snippet of post in this blog and redirect the users to the full post in medium but that sounds like a duplicate effort as of now.</p>

<p>Please head over to my latest posts <a href="https://medium.com/@neilghosh">https://medium.com/@neilghosh</a>.</p>

<p>In future I may migrate all the post hosted here (I came here gtom Blogger.com via wordpress :) ) to my medium page but I am skeptical about being locked to a propriatory platform right now.</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[Moving to medium for better visibility and collaberation]]></summary></entry><entry><title type="html">Add custom ssh key for github</title><link href="https://www.neilghosh.com/2024/11/add-custom-ssh-key-github.html" rel="alternate" type="text/html" title="Add custom ssh key for github" /><published>2024-11-09T00:00:00+00:00</published><updated>2024-11-09T00:00:00+00:00</updated><id>https://www.neilghosh.com/2024/11/add-custom-ssh-key-github</id><content type="html" xml:base="https://www.neilghosh.com/2024/11/add-custom-ssh-key-github.html"><![CDATA[<p>The recommended way of accessing (cloning/fetching/pushing code) github repos via command line is to generate ssh key pair (private key and public key) and <a href="https://docs.github.com/en/authentication/connecting-to-github-with-ssh">setting the public key content in the Github’s settings</a>.</p>

<p>Generating key pair</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh-keygen -t ed25519 -C "Your EMail"
</code></pre></div></div>
<p>Provide the file name this time.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Enter file in which to save the key (/Users/sabyasachi.ghosh/.ssh/id_ed25519): github
</code></pre></div></div>

<p>Once can use the default key generated (without any file name specified) globally for all git hosts, however there is a chance you are using two different git servers and want to keep the keys separate. This becomes really important in cases you are using the same machine for work and personal git repos.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>laptop % ls -ltr ~/.ssh/
total 56
-rw-------@ 1 sabyasachi.ghosh  staff   432 Oct 27 13:20 id_ed25519
-rw-r--r--@ 1 sabyasachi.ghosh  staff   113 Oct 27 13:20 id_ed25519.pub
-rw-------@ 1 sabyasachi.ghosh  staff   411 Nov  9 10:16 github
-rw-r--r--@ 1 sabyasachi.ghosh  staff   102 Nov  9 10:16 github.pub
-rw-r--r--@ 1 sabyasachi.ghosh  staff    84 Nov  9 10:38 config
-rw-------@ 1 sabyasachi.ghosh  staff  1523 Nov  9 10:39 known_hosts
</code></pre></div></div>

<p>In this case you have to explicitly provide the key generated specifically for a git server in <code class="language-plaintext highlighter-rouge">~/.ssh/config</code> file. For example</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Host github.com
  AddKeysToAgent yes
  UseKeychain yes
  IdentityFile ~/.ssh/github
</code></pre></div></div>

<p>Now you can test the connection (even before attempting to clone)</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh -T git@github.com
</code></pre></div></div>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Are you sure you want to continue connecting (yes/no/[fingerprint])? yes
Warning: Permanently added 'github.com' (ED25519) to the list of known hosts.
Hi neilghosh! You've successfully authenticated, but GitHub does not provide shell access.
</code></pre></div></div>

<p>Now we can go ahead and go all git operation.</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[In this post, we will generate generate a custom ssh key and set it for githib.com account.]]></summary></entry><entry><title type="html">Downloading files from GoPro to Desktop using WiFi</title><link href="https://www.neilghosh.com/2024/11/Downloading-files-from-GoPro-via-WiFi.html" rel="alternate" type="text/html" title="Downloading files from GoPro to Desktop using WiFi" /><published>2024-11-08T00:00:00+00:00</published><updated>2024-11-08T00:00:00+00:00</updated><id>https://www.neilghosh.com/2024/11/Downloading-files-from-GoPro-via-WiFi</id><content type="html" xml:base="https://www.neilghosh.com/2024/11/Downloading-files-from-GoPro-via-WiFi.html"><![CDATA[<p>The most convenient way of downloading photos and videos from GoPro is to use the GoPro Quik in mobile and desktop. In Desktop it uses USB cable, however if for some reason it does not work via cable, once can download wirelessly.</p>

<ol>
  <li>Enable Wifi in GoPro. (Fastest way is to connect from mobile app and view media).</li>
  <li>Connect your PC/Mac to the GoPro’s WiFi e.g. “GoPro Hero 10 Black”</li>
  <li>Navigate to http://10.5.5.9/videos/DCIM/100GOPRO/, it should give the directory listing.</li>
  <li>You can download files one by one by right clicking and downloading</li>
  <li>You can use <code class="language-plaintext highlighter-rouge">wget</code> to download in a bulk as well. <code class="language-plaintext highlighter-rouge">wget -r -np -nH -nc -A MP4 "http://10.5.5.9/videos/DCIM/100GOPRO/?dd"</code></li>
</ol>

<p>One can play with <code class="language-plaintext highlighter-rouge">wget</code>’s options to download specific file pattern i.e. extension or even append <code class="language-plaintext highlighter-rouge">dd</code> to the query string to sort the listing in and download oldest file first.</p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[In this post, we will download videos and photos from GoPro using its WiFi to desktop]]></summary></entry><entry><title type="html">Generate Embeddings using Vertext AI and Vector Database</title><link href="https://www.neilghosh.com/2023/12/embeddings-prediction-using-vertext-ai-and-vector-database.html" rel="alternate" type="text/html" title="Generate Embeddings using Vertext AI and Vector Database" /><published>2023-12-02T00:00:00+00:00</published><updated>2023-12-02T00:00:00+00:00</updated><id>https://www.neilghosh.com/2023/12/embeddings-prediction-using-vertext-ai-and-vector-database</id><content type="html" xml:base="https://www.neilghosh.com/2023/12/embeddings-prediction-using-vertext-ai-and-vector-database.html"><![CDATA[<p>Google Cloud Vertex AI’s Multimodal Prediction Models let us create embeddings from Images (or even text for that matter). By default the embeddings are generated as 1408-dimension vectors however this value is configurable.</p>

<p>These embeddings can be stored in a vector database and various queries like finding similar images on the basis of distances can be done on the stored vector data.</p>

<p><img src="/assets/2023/plane-bird-distance.jpg" alt="enter image description here" /></p>

<p>In this post, we will generate embeddings from photos stored in Google Cloud Storage and save them PostgreSQL database with <a href="https://github.com/pgvector/pgvector">pg-vector enxtension</a>. Then we will query for images which are similar to any given images on the data set. We will use a notebook in Collab Enterprise which is a great way of interactively playing with code snippets and iterating like a REPL. It is backed by computing resources (called Runtimes) from Google Cloud which can spin up and scale very quickly. Notebooks in the cloud can also be shared with others who can contribute text and code simultaneously.</p>

<p>Let’s get started …</p>

<h3 id="setting-up">Setting up</h3>
<h4 id="launching-notebook">Launching Notebook.</h4>
<p><a href="https://console.cloud.google.com/vertex-ai/colab/notebooks">Collab Enterprise</a> can be accessed directly under the Vertext AI menu in Google Cloud Console. Once enabled with billing account and all necessary APIs are enabled we should be able to create notebooks.</p>

<h4 id="setup-gcloud">Setup gcloud</h4>
<p>Since we will use various CLI commands from Google Cloud SDK, <code class="language-plaintext highlighter-rouge">gcloud</code> needs to be installed and authorised with the GCP project whose resources will be used.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>!curl https://sdk.cloud.google.com | bash
!gcloud init
!gcloud config set project &lt;project_id&gt;
</code></pre></div></div>

<h4 id="generate-embeddings-from-images">Generate embeddings from Images</h4>
<p>For this we will use the <a href="https://cloud.google.com/vertex-ai/docs/generative-ai/embeddings/get-multimodal-embeddings#api-usage">multimodal API from Vertext AI</a>. This API takes both text and image. In the case of image, it takes either the image data (in base64 encoded bytes) or URL of the GCS object. GCS URLs would take less time to transfer the data from local run-time storage, so we would go for that option.</p>

<p>Following is the API Request Payload. We have kept the dimension to be the minimum supported so that we get a quick and small response for the experiment. Larger dimensions would give us more accuracy while searching at a later stage  by retaining more information from the images into the embedding vectors.</p>

<h4 id="request">Request</h4>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{
  "instances": [
    {
      "image": {
        "gcsUri": "gs://&lt;gcs_bucket&gt;/IMG001.jpg"
      }
    }
  ],
  "parameters": {
    "dimension": 128
  }
}
</code></pre></div></div>
<h4 id="python-client">Python Client</h4>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>location : str = "us-central1",
api_regional_endpoint: str = "us-central1-aiplatform.googleapis.com"):
client_options = {"api_endpoint": api_regional_endpoint}
self.client = aiplatform.gapic.PredictionServiceClient(client_options=client_options)

image_struct = instance.fields['image'].struct_value
image_struct.fields['gcsUri'].string_value = gcs_url
instances = [instance]

parameter = struct_pb2.Struct()
parameter.fields['dimension'].number_value = 128
parameters = parameter

endpoint = (f"projects/{self.project}/locations/{self.location}"
      "/publishers/google/models/multimodalembedding@001")
response = self.client.predict(endpoint=endpoint, instances=instances, parameters=parameters)
</code></pre></div></div>

<p>The response would be an array of numbers, similar to the following</p>
<h4 id="response">Response</h4>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{
  "predictions": [
    {
      "imageEmbedding": [
        0.00262696808,
        -0.00198890246,
        0.0152047109,
        -0.0103145819,
        [...]
        0.0324628279,
        0.0284924973,
        0.011650892,
        -0.00452344026
      ]
    }
  ]
}
</code></pre></div></div>
<p>The above API (python client) only supports one image at a time so that it can be called for each image found in a GCS bucket where we have uploaded the image files. <a href="https://cloud.google.com/vertex-ai/docs/generative-ai/embeddings/batch-prediction-genai-embeddings">There is a Batch API</a> for this but that only supports the text far. This is one of the reasons why we chose to use GCS object URLs directly instead of encoding the image into base64 bytes and sending the full content in the API.</p>

<h3 id="invoke-api-and-save-embeddings">Invoke API and Save Embeddings</h3>
<p>We use Google Cloud Python SDK again to list the images found in the bucket parse the response from the API and save as a CSV file.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bucket_name = "birdwalk"
storage_client = storage.Client()
blobs = storage_client.list_blobs(bucket_name)
for blob in blobs:
	instance = struct_pb2.Struct()
	gcs_url = os.path.join("gs://", bucket_name, blob.name)
	image_struct = instance.fields['image'].struct_value
	image_struct.fields['gcsUri'].string_value = gcs_url

	response = client.get_embedding(image_bytes=image_file_contents, gcs_url=gcs_url)
	
	row = response.image_embedding;
	row.insert(0, blob.name) #add the image name as key
	rows.append(row)

with  open('embeddings.csv', 'w') as f:
write = csv.writer(f)
write.writerows(rows)
</code></pre></div></div>

<h4 id="inspect-the-results">Inspect the results</h4>
<p>We chose to save the result locally and inspect it either by clicking on the file directly in the notebook runtime file system or just loading it to pandas and printing.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>import pandas as pd
DATASET_URL='embeddings.csv'
image_embeddings = pd.read_csv(DATASET_URL, header=None)
image_embeddings.head(5)
</code></pre></div></div>
<h3 id="setup-cloud-sql">Setup Cloud SQL</h3>
<p>We will create a small instance of Cloud SQL and install the pg-vector extension to support the <code class="language-plaintext highlighter-rouge">VECTOR</code> data type.  We chose 1 CPU and 1.7 GB memory to minimise cost as we are not going to store and query a lot of data. Cloud SQL instance is charged as long as it’s up so we can stop the instance once we are done and start it when we intend to use it again. It will still charge for the storage and IP etc but they are negligible as compared to the instance running cost.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    DATASET_URL='embeddings.csv'
    image_embeddings = pd.read_csv(DATASET_URL, header=None)

    loop = asyncio.get_running_loop()
    async with Connector(loop=loop) as connector:
        # Create connection to Cloud SQL database.
        conn: asyncpg.Connection = await connector.connect_async(
            f"{project_id}:{region}:{instance_name}",  # Cloud SQL instance connection name
            "asyncpg",
            user=f"{database_user}",
            password=f"{database_password}",
            db=f"{database_name}",
        )

        await conn.execute("CREATE EXTENSION IF NOT EXISTS vector")
        await register_vector(conn)

        await conn.execute("DROP TABLE IF EXISTS image_embeddings")
        # Create the `product_embeddings` table to store vector embeddings.
        await conn.execute(
            """CREATE TABLE image_embeddings(
                                image_id VARCHAR(1024),
                                content TEXT,
                                embedding vector(128))"""
        )

        # Store all the generated embeddings back into the database.
        for index, row in image_embeddings.iterrows():
            await conn.execute(
                "INSERT INTO image_embeddings (image_id, content, embedding) VALUES ($1, $2, $3)",
                row[0],
                "",
                np.array(row[1:]),
            )
</code></pre></div></div>
<h3 id="query-for-similar-images">Query For Similar Images</h3>
<p>Now we can query the database for similar image to a specific image.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>        result = await conn.fetch(
            '''
              SELECT
                image_id,
                embedding &lt;-&gt; ( SELECT
                                  embedding
                                FROM image_embeddings
                                WHERE image_id = $1) as distance
              FROM image_embeddings
              WHERE image_id != $1
              ORDER BY distance
              LIMIT 5;
            ''',
            image_id )
</code></pre></div></div>

<p>This query essentially takes the name of the image file as <code class="language-plaintext highlighter-rouge">image_id</code> and compares its embeddings with the embeddings of other images and returns the top 5 images (excluding the input image whose distance of course will be zero) whose distance is closer to the supplied image. In this example I wanted to find if there are similar images to the photo of the plane and if you notice in the result, it returns 4 planes of which the first two’s distance is very less ( &lt; 0.2 because it was the same plane taken from different angle) and other two have higher distance (betwene 0.3 to .4) . The last image is actually of a bird hence has an even higher distance( &lt; 0.5). By doing the following changes the results could have been more accurate i.e. distance of the same plane would have been very small  as compared to a that of different plan or a bird for which distance was expected to be very high.</p>

<ul>
  <li>The dimension of the embedding could be increased so that more features of the images could have been used for comparison/distance.</li>
  <li>The input image itself could have been processed (e.g. cropped to the object)  so that the sky which is common in all images couldn’t have dominated the similarity.</li>
</ul>

<p>I’ll soon upload the the fully working notebook (of course Bring Your Own GCP Project).
<!--stackedit_data:
eyJoaXN0b3J5IjpbODA1NDY5Nzc4LC04Mjc0OTg5NDQsMTgxMD
gwNzU3NywtNDYwODMxMTg5LC0xMTEyODcyNjk1LDE5OTI3NDkw
MTcsNzYxODEwMDA0XX0=
--></p>]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[In this post, we will generate embeddings from photos stored in Google Cloud Storage and save them PostgreSQL database with [pg-vector enxtension](https://github.com/pgvector/pgvector). Then we will query for images which are similar to any given images on the data set. We will use a notebook in Collab Enterprise which is a great way of interactively playing with code snippets and iterating like a REPL. It is backed by computing resources (called Runtimes) from Google Cloud which can spin up and scale very quickly. Notebooks in the cloud also can be shared with others who can contribute text and code simultaneously.]]></summary></entry><entry><title type="html">It Has Been A While!</title><link href="https://www.neilghosh.com/2023/04/it-has-been-a-while.html" rel="alternate" type="text/html" title="It Has Been A While!" /><published>2023-04-04T00:00:00+00:00</published><updated>2023-04-04T00:00:00+00:00</updated><id>https://www.neilghosh.com/2023/04/it-has-been-a-while</id><content type="html" xml:base="https://www.neilghosh.com/2023/04/it-has-been-a-while.html"><![CDATA[<p>It has been a while!</p>

<p>I just realised that my last post was in August 2022. That’s nearly 8 months. I doubt if there has been such a long gap in the past between the two posts. Honestly, I don’t have anything specific to post today, definitely not related to tech. I am just trying to create a habit, of writing, at least the content that can be posted publicly. Something like Snapchat streak, just heard about it from one of my 17-year-old cousins though I never used it.  I know resolutions are taken in the new year usually but after all, April is the beginning of the financial year in India and in my opinion, more things reset in April than in January. So it’s not really a bad time for starting anything.</p>

<p>So what’s going on in this world? I actually have no idea, at least it’s hard to articulate whatever bits and pieces I think what’s going on. How do I start putting them down?</p>

<p>One of the ways to start a conversation, especially one-on-one is to ask “What’s on top of your mind?”, not a bad strategy though needless to say the conversation will always start with something on top of my mind unless the agenda is defined for any meeting. Nevertheless, let’s go with that strategy.</p>

<p>I can’t really write anything personal, like relationships, financial goals or even career aspirations at this point but at least mention my world view of mine which is definitely in the top 10 things in mind if not the top 5 - which is probably all occupied with very personal things.</p>

<p>Firstly - The <strong>potential return of Covid</strong> is definitely one of the concerning me right now. Finally, people started to live their lives like the pre-covid era but again there is news. <a href="https://www.ndtv.com/india-news/new-covid-cases-up-by-186-in-maharashtra-4-deaths-in-24-hours-3920000">New Covid Cases Up By 186% In Maharashtra, 4 Deaths In 24 Hours</a>. I don’t even see the chart that used to come in google’s search result till a few months back. The only good thing that happened during covid is people learned to work remotely be it tech or teaching. I see a lot of parents could be returned to work while they were forced to take a break to take care of their children at home. Well, all these are not comparable with the lives lost during covid waves. All I can do is keep an eye on numbers right now and don’t forget some hygiene and behaviour are applicable always be it covid or not. Even if we don’t mask up always, washing hands and unnecessary physical contact should be avoided.</p>

<p>Next, I think the <strong>financial slowdown</strong> had affected a lot of people I know. People have lost their jobs, especially in tech, the very industry which went through great resignation during even peak of the covid. It is unbelievable. Surprisingly the “Product based” companies suffered more than the “Service based” companies which have been always looked down upon in tech industries. Not sure who would have the last laugh. I never thought there is a comparison. Yes, the average salaries of the service companies may be less than the product companies but look at the layoff numbers now. Also, I have so many friends who made their fortune working for services companies for overseas clients only to move to the client location for good if not end up working for the clients themselves.</p>

<p>There are other things like <strong>climate change</strong> that are always a concerning thing year after year.</p>

<p>Hopefully, my next post will be tech related but I am glad I am able to write.</p>

<!--stackedit_data:
eyJoaXN0b3J5IjpbMTU0ODEwMjQzOSw3MjgyOTI3MDldfQ==
-->]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[It has been a while!]]></summary></entry><entry><title type="html">India Community Summit 2022</title><link href="https://www.neilghosh.com/2022/08/India-Community-Summit-2022.html" rel="alternate" type="text/html" title="India Community Summit 2022" /><published>2022-08-28T00:00:00+00:00</published><updated>2022-08-28T00:00:00+00:00</updated><id>https://www.neilghosh.com/2022/08/India-Community-Summit-2022</id><content type="html" xml:base="https://www.neilghosh.com/2022/08/India-Community-Summit-2022.html"><![CDATA[<p><a href="https://www.youtube.com/watch?v=OApF3wqgTEI">India Community Summit 2019</a> was a great experience in Bangalore. This time it was literally the next level. It was held in Ladakh. Not just the sessions and networking during the summit, everyone was super excited to visit Ladakh as its one of the top tourist destinations in India.</p>

<p><img src="/assets/2022/ics2022/IMG_5868.jpg" alt="Plane" /></p>

<p>The agenda of this two and half-day summit was a mix of sessions from special speakers from Google Developer Relations, Community Leaders, Cultural Programs and visits to nearby tourist places. However, the biggest benefit was probably the opportunity to connect with people in person which people have been deprived of lately due to the pandemic.</p>

<p><img src="/assets/2022/ics2022/IMG_5995.jpg" alt="Plane" /></p>

<p>The preparation for the journey involved making sure one is fit for high altitudes like Ladakh and packing a bunch of warm clothes including jackets. The weather was actually bright and sunny and not much of use for the jacket until late evening when it starts to get a bit cold and breezy.</p>

<p><img src="/assets/2022/ics2022/IMG_6020.jpg" alt="Plane" /></p>

<p>The beauty of the Himalayan range can be seen right from the plane to Ladakh. Most flights in fact start from New Delhi. The stay was one of the best hotels in Ladakh with a beautiful view of the Karakoram range through the window of the room.</p>

<p><img src="/assets/2022/ics2022/IMG_6030.jpg" alt="Plane" /></p>

<p>Day 1 when everyone landed from various parts of India was mostly recommended to be spent acclimatising the altitude. So there wasn’t much activity but it was well utilised networking with each other.</p>

<p><img src="/assets/2022/ics2022/IMG_6077.jpg" alt="Plane" /></p>

<p>Day 2 started with very inspiring keynotes from various members of Google Developer Relations and some of the community sessions who presented on some of the designated topics. End of the day there was a trip to the Thikse Monastery which was quite a bit of a climb but the place and the view of Ladakh from the top were definitely worth it.</p>

<p><img src="/assets/2022/ics2022/IMG_6074.jpg" alt="Plane" /></p>

<p>The day ended with the musical performance of Tongue Drum (which everyone in the audience got as a gift as well) by <a href="https://www.instagram.com/karthikmani_drums/?hl=en">Karthik Mani</a> and cultural programs by the Ladakh Art and Culture Group.</p>

<p><img src="/assets/2022/ics2022/DSC03977.jpeg" alt="Plane" /></p>

<p>Day 3 continued with some of the breakout sessions for GDEs and the remaining community sessions. It also had fun team-building activities. Post lunch we again set out for local sightseeing including the Shanti Stupa and Ladakh Palace which was very close to Ladakh market as well. End of the day 3 involved a show by Magician/Mentalist Suhani Shah and the “gala dinner”.</p>

<p><img src="/assets/2022/ics2022/IMG_6239.jpg" alt="Plane" /></p>

<!--stackedit_data:
eyJoaXN0b3J5IjpbLTE1ODI1NTA1MTQsLTYyOTg3NjcwMywtMz
kxNjkzNDc4LDE2Mzg4MDM1NTFdfQ==
-->]]></content><author><name>Neil Ghosh</name><email>neil.ghosh@gmail.com</email></author><summary type="html"><![CDATA[After a gap of 3 years due to pandemic the India Community Summit was organized by Google Developers at Ladakh. GDG Organizers, Developer Experts and Student Club Leads across India were part of it]]></summary></entry></feed>